时间轴
时间轴
2025-11-20
init
2026-07-25
本文介绍了Linux内存管理的核心概念与硬件交互流程,包括地址空间隔离问题、分段与分页机制,以及逻辑地址、线性地址、虚拟地址和物理地址的区别。文章详细阐述了CPU、MMU、TLB、Cache、主存储器、页表和Swap等关键硬件模块的作用,并说明了地址翻译、数据读取及缺页中断的处理流程。此外,还总结了用户空间与内核空间的内存管理机制,如系统调用、VMA管理、延迟分配、匿名页、页缓存、页面回收和SLAB分配器等。
关于地址
地址空间不隔离
1.恶意的进程可以随意修改别的进程的内存
2.内存使用的效率很低,如当内存短缺时需要把进程中的所有数据交换到交换分区
早期内存的使用方法
- 分段(主要思想:将虚拟地址空间与物理地址空间做一一的映射,程序运行需要全部装载到内存中)
- 分页(主要思想:程序运行时,需要哪个页面才分配哪个页面,即按需分配,长期不需要的可以交换到磁盘中)
地址概念:
逻辑地址(Intel 专用术语,产生的和段相关的偏移地址那个部分)
线性地址(Intel 专用术语,逻辑地址转换到物理地址的一个中间层,在分段中,逻辑地址是段偏移地址,再加上基地址即变成线性地址)
虚拟地址 (逻辑地址和线性地址统称虚拟地址)
物理地址(CPU 通过外部总线访问物理内存需要的地址)
进程地址空间

核心硬件模块
CPU:执行程序指令的主体。CPU 内部寄存器和计算单元处理的都是虚拟地址(Virtual Address),无法直接操作物理内存条。
MMU (Memory Management Unit,内存管理单元):位于 CPU 芯片内部的硬件,专门负责将 CPU 发出的 虚拟地址 转换(翻译)为 物理地址。
TLB (Translation Lookaside Buffer,页表缓存):MMU 内部的一块极高速 Cache,专门用来缓存最近使用过的“虚拟地址 物理地址”映射关系,也称快表。
一级缓存 (L1 Cache) & 二级缓存 (L2 Cache):位于 CPU 和主存储器之间的高速 SRAM 存储器。
- 一级缓存:速度最快,紧靠 MMU。
- 物理索引 / 物理 Tag:图中提示,一级缓存与二级缓存之间使用物理地址(或物理索引/Tag)进行寻址与数据校验。
主存储器 (Main Memory / DRAM):即系统中的物理内存条,用于存放系统和进程运行时的指令与数据。
- 页表 (Page Table):存放在主存储器中的映射数据结构(多级页表)。当 TLB 没命中时,MMU 需要查询主存中的页表来查找地址映射。
Swap (交换空间/磁盘交换区):位于磁盘/SSD 上的存储区域。当主存储器空间不足时,内核会将不常用的内存页临时换出(Swap out)到这里;需要时再换入(Swap in)到主存。
硬件工作与交互流程
地址翻译流程(MMU TLB / 页表)
CPU 发出虚拟地址:CPU 执行访存指令,将虚拟地址发送给 MMU。
TLB Hit (TLB 命中):
- MMU 首先查询 TLB。如果 TLB 中存在该虚拟地址的映射,称为 TLB Hit,MMU 可以在极短时间内(通常 1 个 CPU 时钟周期内)直接获得物理地址。
TLB Miss (TLB 未命中):
如果 TLB 中没有该映射,称为 TLB Miss。
MMU 必须沿着箭头向下访问主存储器中的页表(通过 Page Table Walk 机制),找到对应的物理地址,并顺便更新到 TLB 中,以便下次快速访问。
数据读取流程(MMU Cache 主存)
访问 Cache:MMU 拿到转换后的物理地址后,去查询一级缓存和二级缓存。
- 如果 Cache 命中(Cache Hit),直接将数据返回给 CPU,无需访问真正的物理内存。
访问主存储器:如果 Cache 缺失(Cache Miss),硬件会去访问主存储器,将数据加载到 Cache 并返回 CPU。
主存与磁盘数据交换(主存储器 Swap)
如果 CPU 访问的页表项显示该页面不在物理内存中(如已经被 Swap 到磁盘,或尚未分配物理页),会触发 缺页中断(Page Fault)。
操作系统介入后,将数据从磁盘的 Swap 区域 读取并重新装载回主存储器,更新页表,随后 CPU 重新执行该访存指令。
内存管理概述
内存管理模块概述

用户空间 (User Space)
用户进程:运行在用户态的应用程序实例。用户进程无法直接访问物理内存,必须通过虚拟地址空间进行内存操作。
malloc / mmap / mlock / madvise / mremap / ...:C 标准库(如 glibc)暴露给开发者的内存管理 API。malloc/free:常用的动态内存分配与释放接口(底层基于brk或mmap)。mmap:将文件或设备映射至进程的虚拟地址空间,也可用于分配大块匿名内存。mlock:将指定范围的虚拟内存锁在物理内存中,防止其被 swap 交换到磁盘。madvise:向内核提供内存使用建议(如顺向读取、随机读取、可释放等),辅助内核优化管理。mremap:扩大或缩小现有的虚拟内存映射区域。
内核空间(Kernel Space)
- 系统调用 (Syscalls):连接用户空间与内核空间的桥梁。通过 CPU 中断/异常机制(如
syscall指令)从用户态切换至内核态。sys_brk:修改进程数据段(heap)顶部的边界值,实现堆小块内存的扩展与缩减。sys_mmap:在内核中创建并建立新的虚拟内存区域映射(VMA)。sys_madvise:接收用户态给出的内存建议并更改对应的 VMA 标志。
vma管理 (Virtual Memory Area):- 内核使用
struct vm_area_struct数据结构来管理进程的一段连续虚拟地址空间(如代码段、数据段、堆、栈等)。 - 负责检查虚拟地址的有效性、访问权限(读/写/执行)及映射类型
- 内核使用
- 缺页中断 (Page Fault Handler):
- 延迟分配(Lazy Allocation)机制:当进程申请内存时,内核仅分配虚拟地址(VMA)而并不立即分配物理内存。
- 当 CPU 首次访问未建立物理映射的虚拟地址时,会触发 缺页异常,内核通过该模块拦截并分配真正的物理页框,随后建立页表映射。
- 匿名页面 (Anonymous Page):
- 没有文件背景的内存页(例如进程的堆、栈、BSS 段、
malloc申请的内存)。 - 交换(Swap)时会被写入 Swap 分区/文件。
- 没有文件背景的内存页(例如进程的堆、栈、BSS 段、
page cache(页缓存):- 用于缓存磁盘文件数据的内存页,比如视频的缓存。
- 通过将文件内容保存在内存中,极大地提高了磁盘 I/O 的读写性能;当内存不足时可直接写回磁盘并释放。
- 页面回收 (Page Reclamation):
- 当系统物理内存紧张时,由内核线程(如
kswapd)或直接回收(Direct Reclaim)机制触发。 - 负责释放脏页(写回磁盘)、回收
page cache以及将匿名页 Swap 到磁盘,以腾出可用物理页。
- 当系统物理内存紧张时,由内核线程(如
slab(SLAB / SLUB / SLOB 分配器):- 针对内核小对象(如
task_struct,mm_struct等结构体)的内存分配器。 - 向伙伴系统一次性申请大块物理页,然后再细分为固定大小的小内存块进行重复利用,避免内存碎片化并提高分配效率(内核中的
kmalloc即依赖于此)
- 针对内核小对象(如
- 伙伴系统(页面分配器 / Buddy System):
- Linux 内核管理物理内存最底层的核心算法。
- 按 个连续物理页(Page Frame)为单位管理物理内存,专门解决物理内存的外碎片问题。所有上层(SLAB、VMA 缺页等)的物理页申请最终都会落到伙伴系统上。
- 页表管理(内核页表和进程页表):
- 维护虚拟地址(VA)到物理地址(PA)映射关系的数据结构(如四级或五级页表:PGD P4D PUD PMD PTE)。
- 包括所有进程独立的用户空间页表以及系统全局共享的内核空间页表。
- 反向映射 (RMAP - Reverse Mapping):
- 常规映射是“虚拟地址 物理地址”。反向映射允许内核通过一个物理页(
struct page)快速反查出有哪些进程的哪些虚拟地址映射到了这个页。在页面回收、页迁移和 Swap 时非常关键。
- 常规映射是“虚拟地址 物理地址”。反向映射允许内核通过一个物理页(
- KSM (Kernel Samepage Merging - 内核同页合并):
- 一种内存去重机制。内核定期扫描内容完全相同的匿名物理页,将其合并为一个只读共享页(采用 Copy-on-Write 机制)。常用于虚拟机(KVM)场景以节省内存。
- Huge Page (大页/巨页):
- 标准物理页通常为 4KB。大页(如 2MB 或 1GB)可以显著减少页表项数量,提高 TLB 命中率,降低高内存消耗应用(如数据库、高性能计算)的地址转换开销。
- 页迁移 (Page Migration):
- 将一个物理页的内容移动到另一个物理页,并更新所有相关的页表映射。常用于 NUMA 节点的内存平衡、内存热插拔以及内存规整。
- 内存规整 (Compaction):
- 解决伙伴系统的外部碎片问题。通过将分散的已用物理页移动到一起,拼凑出连续的大块空白物理页,以满足大页或连续内存的分配需求。
- OOM (Out-of-Memory Killer):
- 系统的最后防线。当物理内存和 Swap 彻底耗尽且无法回收时,OOM Killer 会根据评分算法选择并杀死分值最高(通常是占用内存最多)的进程,以防止整个系统崩溃。
- 系统调用 (Syscalls):连接用户空间与内核空间的桥梁。通过 CPU 中断/异常机制(如
硬件层 (Hardware Layer)
MMU (Memory Management Unit) & TLB (Translation Lookaside Buffer):
- MMU(内存管理单元):CPU 内部的硬件电路,负责在运行时自动将 CPU 发出的虚拟地址(VA)转换为物理地址(PA)。
- TLB(页表缓存):MMU 内部的高速缓存,用于缓存最近使用过的“虚拟地址 物理地址”映射关系,从而加速地址转换速度。
cache(CPU L1 / L2 / L3 缓存):- 位于 CPU 与物理内存之间的高速 SRAM 缓存,自动缓存最近频繁访问的物理内存数据,极大降低 CPU 访问 DRAM 的等待延迟。
物理内存 (Physical Memory / DRAM):
- 计算机实际安装的内存条硬件(RAM)。伙伴系统将这部分物理实体划分为多个 Node 和 Zone(如 Zone DMA, Zone Normal, Zone HighMem 等)进行统筹管理。
从进程角度来看内存管理

典型的 32 位 Linux 系统虚拟地址空间布局:
用户空间(0-3G):
- 代码段 & 数据段:存放程序的可执行指令和初始化数据。
- 堆空间:用于动态内存分配(如
malloc),向高地址方向增长。 - mmap 空间:用于文件映射、共享内存等,向低地址方向增长。
- 栈空间:用于函数调用和局部变量,向低地址方向增长。
内核空间(3G-4G):
- 所有进程共享这部分地址空间,用于内核代码、数据和临时映射。

虚拟地址布局
物理内存映射:
线性映射:内核将低端物理内存(如
ZONE_NORMAL)直接、线性地映射到内核地址空间的固定区域,访问速度快。高端映射:对于高端物理内存(如
ZONE_HIGHMEM),内核需要时才将其临时映射到内核地址空间的高端部分。
进程层面:
task_struct与mm_structtask_struct:每个进程在内核中都由一个task_struct结构体描述,它包含了进程的所有信息,其中的mm成员指向了进程的内存描述符。mm_struct:这是进程的内存描述符,是管理进程虚拟地址空间的核心数据结构。它主要包含两个关键成员:mmap:指向进程的虚拟内存区域(VMA)链表或红黑树的根。pgd:指向进程页全局目录(Page Global Directory),是页表的顶级入口。
虚拟内存区域(VMA)管理
VMA(Virtual Memory Area):内核用
vm_area_struct结构体来描述一段连续的虚拟地址空间。每个 VMA 代表一段具有相同属性(如可读、可写、可执行)的虚拟内存,例如代码段、数据段、堆、栈、mmap 映射区等。mm_struct通过mmap成员将所有 VMA 组织起来,方便内核进行查找、管理和操作。
mem_map[]数组:内核用一个全局的mem_map数组来管理所有物理内存页,数组中的每一个元素都是一个struct page结构体,代表一个物理页帧。ZONE 管理:物理内存被划分为不同的内存管理区(ZONE),例如
ZONE_DMA、ZONE_NORMAL、ZONE_HIGHMEM等,每个区有不同的用途和管理方式。
内存分配器

从数据结构关系来看内存管理

| 数据结构 | 主要定义文件 | 补充说明 |
|---|---|---|
mm_struct | include/linux/mm_types.h | 也会在include/linux/mm.h中被广泛引用和操作 |
vm_area_struct(VMA) | include/linux/mm_types.h | 描述一段连续的虚拟内存区域 |
struct page | include/linux/mm_types.h | 早期内核版本中定义在include/linux/mm.h,新版本移至mm_types.h |
struct zone | include/linux/mmzone.h | 描述物理内存管理区(如 DMA、NORMAL、HIGHMEM) |
struct pglist_data(pgdata) | include/linux/mmzone.h | NUMA 节点的内存描述符,管理该节点下的所有 zone |
mem_map[] | mm/memory.c | 全局物理页数组,其地址由内核初始化时确定,每个 NUMA 节点也有自己的node_mem_map |
pte_t/ 页表项 | arch/arm64/include/asm/pgtable-types.h | 页表项类型与页表操作是架构相关的 |
struct mm_struct
123456789101112131415161718192021222324252627282930313233343536373839404142434445464748495051525354555657585960616263646566676869707172737475767778798081828384858687888990919293949596979899100101102103104105106107108109110111112113114115116117118119120121122123124125126127128129130131132133134135136137138139140141142143144145146147148149150151152153154155156157158159160161162163164165166167168169170171172173174175176177178179180181182183184185186187188189190191 | // include/linux/mm_types.hstruct mm_struct { struct { struct vm_area_struct *mmap; /* list of VMAs */ struct rb_root mm_rb; u64 vmacache_seqnum; /* per-thread vmacache */ unsigned long (*get_unmapped_area) (struct file *filp, unsigned long addr, unsigned long len, unsigned long pgoff, unsigned long flags); unsigned long mmap_base; /* base of mmap area */ unsigned long mmap_legacy_base; /* base of mmap area in bottom-up allocations */ /* Base addresses for compatible mmap() */ unsigned long mmap_compat_base; unsigned long mmap_compat_legacy_base; unsigned long task_size; /* size of task vm space */ unsigned long highest_vm_end; /* highest vma end address */ pgd_t * pgd; /** * @membarrier_state: Flags controlling membarrier behavior. * * This field is close to @pgd to hopefully fit in the same * cache-line, which needs to be touched by switch_mm(). */ atomic_t membarrier_state; /** * @mm_users: The number of users including userspace. * * Use mmget()/mmget_not_zero()/mmput() to modify. When this * drops to 0 (i.e. when the task exits and there are no other * temporary reference holders), we also release a reference on * @mm_count (which may then free the &struct mm_struct if * @mm_count also drops to 0). */ atomic_t mm_users; /** * @mm_count: The number of references to &struct mm_struct * (@mm_users count as 1). * * Use mmgrab()/mmdrop() to modify. When this drops to 0, the * &struct mm_struct is freed. */ atomic_t mm_count; atomic_long_t pgtables_bytes; /* PTE page table pages */ int map_count; /* number of VMAs */ spinlock_t page_table_lock; /* Protects page tables and some * counters */ /* * With some kernel config, the current mmap_lock's offset * inside 'mm_struct' is at 0x120, which is very optimal, as * its two hot fields 'count' and 'owner' sit in 2 different * cachelines, and when mmap_lock is highly contended, both * of the 2 fields will be accessed frequently, current layout * will help to reduce cache bouncing. * * So please be careful with adding new fields before * mmap_lock, which can easily push the 2 fields into one * cacheline. */ struct rw_semaphore mmap_lock; struct list_head mmlist; /* List of maybe swapped mm's. These * are globally strung together off * init_mm.mmlist, and are protected * by mmlist_lock */ unsigned long hiwater_rss; /* High-watermark of RSS usage */ unsigned long hiwater_vm; /* High-water virtual memory usage */ unsigned long total_vm; /* Total pages mapped */ unsigned long locked_vm; /* Pages that have PG_mlocked set */ atomic64_t pinned_vm; /* Refcount permanently increased */ unsigned long data_vm; /* VM_WRITE & ~VM_SHARED & ~VM_STACK */ unsigned long exec_vm; /* VM_EXEC & ~VM_WRITE & ~VM_STACK */ unsigned long stack_vm; /* VM_STACK */ unsigned long def_flags; /** * @write_protect_seq: Locked when any thread is write * protecting pages mapped by this mm to enforce a later COW, * for instance during page table copying for fork(). */ seqcount_t write_protect_seq; spinlock_t arg_lock; /* protect the below fields */ unsigned long start_code, end_code, start_data, end_data; unsigned long start_brk, brk, start_stack; unsigned long arg_start, arg_end, env_start, env_end; unsigned long saved_auxv[AT_VECTOR_SIZE]; /* for /proc/PID/auxv */ /* * Special counters, in some configurations protected by the * page_table_lock, in other configurations by being atomic. */ struct mm_rss_stat rss_stat; struct linux_binfmt *binfmt; /* Architecture-specific MM context */ mm_context_t context; unsigned long flags; /* Must use atomic bitops to access */ struct core_state *core_state; /* coredumping support */ spinlock_t ioctx_lock; struct kioctx_table __rcu *ioctx_table; /* * "owner" points to a task that is regarded as the canonical * user/owner of this mm. All of the following must be true in * order for it to be changed: * * current == mm->owner * current->mm != mm * new_owner->mm == mm * new_owner->alloc_lock is held */ struct task_struct __rcu *owner; struct user_namespace *user_ns; /* store ref to file /proc/<pid>/exe symlink points to */ struct file __rcu *exe_file; struct mmu_notifier_subscriptions *notifier_subscriptions; pgtable_t pmd_huge_pte; /* protected by page_table_lock */ /* * numa_next_scan is the next time that the PTEs will be marked * pte_numa. NUMA hinting faults will gather statistics and * migrate pages to new nodes if necessary. */ unsigned long numa_next_scan; /* Restart point for scanning and setting pte_numa */ unsigned long numa_scan_offset; /* numa_scan_seq prevents two threads setting pte_numa */ int numa_scan_seq; /* * An operation with batched TLB flushing is going on. Anything * that can move process memory needs to flush the TLB when * moving a PROT_NONE or PROT_NUMA mapped page. */ atomic_t tlb_flush_pending; /* See flush_tlb_batched_pending() */ bool tlb_flush_batched; struct uprobes_state uprobes_state; atomic_long_t hugetlb_usage; struct work_struct async_put_work; u32 pasid; } __randomize_layout; /* * The mm_cpumask needs to be at the end of mm_struct, because it * is dynamically sized based on nr_cpu_ids. */ unsigned long cpu_bitmap[];}; |
struct vm_area_struct
123456789101112131415161718192021222324252627282930313233343536373839404142434445464748495051525354555657585960616263646566676869707172737475767778 | // include/linux/mm_types.h/* * This struct describes a virtual memory area. There is one of these * per VM-area/task. A VM area is any part of the process virtual memory * space that has a special rule for the page-fault handlers (ie a shared * library, the executable area etc). */struct vm_area_struct { /* The first cache line has the info for VMA tree walking. */ unsigned long vm_start; /* Our start address within vm_mm. */ unsigned long vm_end; /* The first byte after our end address within vm_mm. */ /* linked list of VM areas per task, sorted by address */ struct vm_area_struct *vm_next, *vm_prev; struct rb_node vm_rb; /* * Largest free memory gap in bytes to the left of this VMA. * Either between this VMA and vma->vm_prev, or between one of the * VMAs below us in the VMA rbtree and its ->vm_prev. This helps * get_unmapped_area find a free area of the right size. */ unsigned long rb_subtree_gap; /* Second cache line starts here. */ struct mm_struct *vm_mm; /* The address space we belong to. */ /* * Access permissions of this VMA. * See vmf_insert_mixed_prot() for discussion. */ pgprot_t vm_page_prot; unsigned long vm_flags; /* Flags, see mm.h. */ /* * For areas with an address space and backing store, * linkage into the address_space->i_mmap interval tree. */ struct { struct rb_node rb; unsigned long rb_subtree_last; } shared; /* * A file's MAP_PRIVATE vma can be in both i_mmap tree and anon_vma * list, after a COW of one of the file pages. A MAP_SHARED vma * can only be in the i_mmap tree. An anonymous MAP_PRIVATE, stack * or brk vma (with NULL file) can only be in an anon_vma list. */ struct list_head anon_vma_chain; /* Serialized by mmap_lock & * page_table_lock */ struct anon_vma *anon_vma; /* Serialized by page_table_lock */ /* Function pointers to deal with this struct. */ const struct vm_operations_struct *vm_ops; /* Information about our backing store: */ unsigned long vm_pgoff; /* Offset (within vm_file) in PAGE_SIZE units */ struct file * vm_file; /* File we map to (can be NULL). */ void * vm_private_data; /* was vm_pte (shared mem) */ atomic_long_t swap_readahead_info; struct vm_region *vm_region; /* NOMMU mapping region */ struct mempolicy *vm_policy; /* NUMA policy for the VMA */ struct vm_userfaultfd_ctx vm_userfaultfd_ctx;} __randomize_layout; |
struct page
123456789101112131415161718192021222324252627282930313233343536373839404142434445464748495051525354555657585960616263646566676869707172737475767778798081828384858687888990919293949596979899100101102103104105106107108109110111112113114115116117118119120121122123124125126127128129130131132133134135136137138139140141142143144145146147148149150151152153154155156157158159160161162163164165166167168169170171172173174175176177178179180181182183184185186187188189190191192193194195196197198199200201202203204205206207208209210211212213 | // include/linux/mm_types.h/* * Each physical page in the system has a struct page associated with * it to keep track of whatever it is we are using the page for at the * moment. Note that we have no way to track which tasks are using * a page, though if it is a pagecache page, rmap structures can tell us * who is mapping it. * * If you allocate the page using alloc_pages(), you can use some of the * space in struct page for your own purposes. The five words in the main * union are available, except for bit 0 of the first word which must be * kept clear. Many users use this word to store a pointer to an object * which is guaranteed to be aligned. If you use the same storage as * page->mapping, you must restore it to NULL before freeing the page. * * If your page will not be mapped to userspace, you can also use the four * bytes in the mapcount union, but you must call page_mapcount_reset() * before freeing it. * * If you want to use the refcount field, it must be used in such a way * that other CPUs temporarily incrementing and then decrementing the * refcount does not cause problems. On receiving the page from * alloc_pages(), the refcount will be positive. * * If you allocate pages of order > 0, you can use some of the fields * in each subpage, but you may need to restore some of their values * afterwards. * * SLUB uses cmpxchg_double() to atomically update its freelist and * counters. That requires that freelist & counters be adjacent and * double-word aligned. We align all struct pages to double-word * boundaries, and ensure that 'freelist' is aligned within the * struct. */struct page { unsigned long flags; /* Atomic flags, some possibly * updated asynchronously */ /* * Five words (20/40 bytes) are available in this union. * WARNING: bit 0 of the first word is used for PageTail(). That * means the other users of this union MUST NOT use the bit to * avoid collision and false-positive PageTail(). */ union { struct { /* Page cache and anonymous pages */ /** * @lru: Pageout list, eg. active_list protected by * lruvec->lru_lock. Sometimes used as a generic list * by the page owner. */ struct list_head lru; /* See page-flags.h for PAGE_MAPPING_FLAGS */ struct address_space *mapping; pgoff_t index; /* Our offset within mapping. */ /** * @private: Mapping-private opaque data. * Usually used for buffer_heads if PagePrivate. * Used for swp_entry_t if PageSwapCache. * Indicates order in the buddy system if PageBuddy. */ unsigned long private; }; struct { /* page_pool used by netstack */ /** * @pp_magic: magic value to avoid recycling non * page_pool allocated pages. */ unsigned long pp_magic; struct page_pool *pp; unsigned long _pp_mapping_pad; unsigned long dma_addr; union { /** * dma_addr_upper: might require a 64-bit * value on 32-bit architectures. */ unsigned long dma_addr_upper; /** * For frag page support, not supported in * 32-bit architectures with 64-bit DMA. */ atomic_long_t pp_frag_count; }; }; struct { /* slab, slob and slub */ union { struct list_head slab_list; struct { /* Partial pages */ struct page *next; int pages; /* Nr of pages left */ int pobjects; /* Approximate count */ short int pages; short int pobjects; }; }; struct kmem_cache *slab_cache; /* not slob */ /* Double-word boundary */ void *freelist; /* first free object */ union { void *s_mem; /* slab: first object */ unsigned long counters; /* SLUB */ struct { /* SLUB */ unsigned inuse:16; unsigned objects:15; unsigned frozen:1; }; }; }; struct { /* Tail pages of compound page */ unsigned long compound_head; /* Bit zero is set */ /* First tail page only */ unsigned char compound_dtor; unsigned char compound_order; atomic_t compound_mapcount; unsigned int compound_nr; /* 1 << compound_order */ }; struct { /* Second tail page of compound page */ unsigned long _compound_pad_1; /* compound_head */ atomic_t hpage_pinned_refcount; /* For both global and memcg */ struct list_head deferred_list; }; struct { /* Page table pages */ unsigned long _pt_pad_1; /* compound_head */ pgtable_t pmd_huge_pte; /* protected by page->ptl */ unsigned long _pt_pad_2; /* mapping */ union { struct mm_struct *pt_mm; /* x86 pgds only */ atomic_t pt_frag_refcount; /* powerpc */ }; spinlock_t *ptl; spinlock_t ptl; }; struct { /* ZONE_DEVICE pages */ /** @pgmap: Points to the hosting device page map. */ struct dev_pagemap *pgmap; void *zone_device_data; /* * ZONE_DEVICE private pages are counted as being * mapped so the next 3 words hold the mapping, index, * and private fields from the source anonymous or * page cache page while the page is migrated to device * private memory. * ZONE_DEVICE MEMORY_DEVICE_FS_DAX pages also * use the mapping, index, and private fields when * pmem backed DAX files are mapped. */ }; /** @rcu_head: You can use this to free a page by RCU. */ struct rcu_head rcu_head; }; union { /* This union is 4 bytes in size. */ /* * If the page can be mapped to userspace, encodes the number * of times this page is referenced by a page table. */ atomic_t _mapcount; /* * If the page is neither PageSlab nor mappable to userspace, * the value stored here may help determine what this page * is used for. See page-flags.h for a list of page types * which are currently stored here. */ unsigned int page_type; unsigned int active; /* SLAB */ int units; /* SLOB */ }; /* Usage count. *DO NOT USE DIRECTLY*. See page_ref.h */ atomic_t _refcount; unsigned long memcg_data; /* * On machines where all RAM is mapped into kernel address space, * we can simply calculate the virtual address. On machines with * highmem some memory is mapped into kernel virtual memory * dynamically, so we need a place to store that address. * Note that this field could be 16 bits on x86 ... ;) * * Architectures with slow multiplication can define * WANT_PAGE_VIRTUAL in asm/page.h */ void *virtual; /* Kernel virtual address (NULL if not kmapped, ie. highmem) */ int _last_cpupid;} _struct_page_alignment; |
struct zone
123456789101112131415161718192021222324252627282930313233343536373839404142434445464748495051525354555657585960616263646566676869707172737475767778798081828384858687888990919293949596979899100101102103104105106107108109110111112113114115116117118119120121122123124125126127128129130131132133134135136137138139140141142143144145146147148149150151152153154155156157158159160161162163164165166167168169170171 | // include/linux/mmzone.hstruct zone { /* Read-mostly fields */ /* zone watermarks, access with *_wmark_pages(zone) macros */ unsigned long _watermark[NR_WMARK]; unsigned long watermark_boost; unsigned long nr_reserved_highatomic; /* * We don't know if the memory that we're going to allocate will be * freeable or/and it will be released eventually, so to avoid totally * wasting several GB of ram we must reserve some of the lower zone * memory (otherwise we risk to run OOM on the lower zones despite * there being tons of freeable ram on the higher zones). This array is * recalculated at runtime if the sysctl_lowmem_reserve_ratio sysctl * changes. */ long lowmem_reserve[MAX_NR_ZONES]; int node; struct pglist_data *zone_pgdat; struct per_cpu_pages __percpu *per_cpu_pageset; struct per_cpu_zonestat __percpu *per_cpu_zonestats; /* * the high and batch values are copied to individual pagesets for * faster access */ int pageset_high; int pageset_batch; /* * Flags for a pageblock_nr_pages block. See pageblock-flags.h. * In SPARSEMEM, this map is stored in struct mem_section */ unsigned long *pageblock_flags; /* zone_start_pfn == zone_start_paddr >> PAGE_SHIFT */ unsigned long zone_start_pfn; /* * spanned_pages is the total pages spanned by the zone, including * holes, which is calculated as: * spanned_pages = zone_end_pfn - zone_start_pfn; * * present_pages is physical pages existing within the zone, which * is calculated as: * present_pages = spanned_pages - absent_pages(pages in holes); * * present_early_pages is present pages existing within the zone * located on memory available since early boot, excluding hotplugged * memory. * * managed_pages is present pages managed by the buddy system, which * is calculated as (reserved_pages includes pages allocated by the * bootmem allocator): * managed_pages = present_pages - reserved_pages; * * cma pages is present pages that are assigned for CMA use * (MIGRATE_CMA). * * So present_pages may be used by memory hotplug or memory power * management logic to figure out unmanaged pages by checking * (present_pages - managed_pages). And managed_pages should be used * by page allocator and vm scanner to calculate all kinds of watermarks * and thresholds. * * Locking rules: * * zone_start_pfn and spanned_pages are protected by span_seqlock. * It is a seqlock because it has to be read outside of zone->lock, * and it is done in the main allocator path. But, it is written * quite infrequently. * * The span_seq lock is declared along with zone->lock because it is * frequently read in proximity to zone->lock. It's good to * give them a chance of being in the same cacheline. * * Write access to present_pages at runtime should be protected by * mem_hotplug_begin/end(). Any reader who can't tolerant drift of * present_pages should get_online_mems() to get a stable value. */ atomic_long_t managed_pages; unsigned long spanned_pages; unsigned long present_pages; unsigned long present_early_pages; unsigned long cma_pages; const char *name; /* * Number of isolated pageblock. It is used to solve incorrect * freepage counting problem due to racy retrieving migratetype * of pageblock. Protected by zone->lock. */ unsigned long nr_isolate_pageblock; /* see spanned/present_pages for more description */ seqlock_t span_seqlock; int initialized; /* Write-intensive fields used from the page allocator */ ZONE_PADDING(_pad1_) /* free areas of different sizes */ struct free_area free_area[MAX_ORDER]; /* zone flags, see below */ unsigned long flags; /* Primarily protects free_area */ spinlock_t lock; /* Write-intensive fields used by compaction and vmstats. */ ZONE_PADDING(_pad2_) /* * When free pages are below this point, additional steps are taken * when reading the number of free pages to avoid per-cpu counter * drift allowing watermarks to be breached */ unsigned long percpu_drift_mark; /* pfn where compaction free scanner should start */ unsigned long compact_cached_free_pfn; /* pfn where compaction migration scanner should start */ unsigned long compact_cached_migrate_pfn[ASYNC_AND_SYNC]; unsigned long compact_init_migrate_pfn; unsigned long compact_init_free_pfn; /* * On compaction failure, 1<<compact_defer_shift compactions * are skipped before trying again. The number attempted since * last failure is tracked with compact_considered. * compact_order_failed is the minimum compaction failed order. */ unsigned int compact_considered; unsigned int compact_defer_shift; int compact_order_failed; /* Set to true when the PG_migrate_skip bits should be cleared */ bool compact_blockskip_flush; bool contiguous; ZONE_PADDING(_pad3_) /* Zone statistics */ atomic_long_t vm_stat[NR_VM_ZONE_STAT_ITEMS]; atomic_long_t vm_numa_event[NR_VM_NUMA_EVENT_ITEMS];} ____cacheline_internodealigned_in_smp; |
struct pglist_data
123456789101112131415161718192021222324252627282930313233343536373839404142434445464748495051525354555657585960616263646566676869707172737475767778798081828384858687888990919293949596979899100101102103104105106107108109110111112113114 | // include/linux/mmzone.h/* * On NUMA machines, each NUMA node would have a pg_data_t to describe * it's memory layout. On UMA machines there is a single pglist_data which * describes the whole memory. * * Memory statistics and page replacement data structures are maintained on a * per-zone basis. */typedef struct pglist_data { /* * node_zones contains just the zones for THIS node. Not all of the * zones may be populated, but it is the full list. It is referenced by * this node's node_zonelists as well as other node's node_zonelists. */ struct zone node_zones[MAX_NR_ZONES]; /* * node_zonelists contains references to all zones in all nodes. * Generally the first zones will be references to this node's * node_zones. */ struct zonelist node_zonelists[MAX_ZONELISTS]; int nr_zones; /* number of populated zones in this node */ struct page *node_mem_map; struct page_ext *node_page_ext; /* * Must be held any time you expect node_start_pfn, * node_present_pages, node_spanned_pages or nr_zones to stay constant. * Also synchronizes pgdat->first_deferred_pfn during deferred page * init. * * pgdat_resize_lock() and pgdat_resize_unlock() are provided to * manipulate node_size_lock without checking for CONFIG_MEMORY_HOTPLUG * or CONFIG_DEFERRED_STRUCT_PAGE_INIT. * * Nests above zone->lock and zone->span_seqlock */ spinlock_t node_size_lock; unsigned long node_start_pfn; unsigned long node_present_pages; /* total number of physical pages */ unsigned long node_spanned_pages; /* total size of physical page range, including holes */ int node_id; wait_queue_head_t kswapd_wait; wait_queue_head_t pfmemalloc_wait; struct task_struct *kswapd; /* Protected by mem_hotplug_begin/end() */ int kswapd_order; enum zone_type kswapd_highest_zoneidx; int kswapd_failures; /* Number of 'reclaimed == 0' runs */ int kcompactd_max_order; enum zone_type kcompactd_highest_zoneidx; wait_queue_head_t kcompactd_wait; struct task_struct *kcompactd; bool proactive_compact_trigger; /* * This is a per-node reserve of pages that are not available * to userspace allocations. */ unsigned long totalreserve_pages; /* * node reclaim becomes active if more unmapped pages exist. */ unsigned long min_unmapped_pages; unsigned long min_slab_pages; /* Write-intensive fields used by page reclaim */ ZONE_PADDING(_pad1_) /* * If memory initialisation on large machines is deferred then this * is the first PFN that needs to be initialised. */ unsigned long first_deferred_pfn; struct deferred_split deferred_split_queue; /* Fields commonly accessed by the page reclaim scanner */ /* * NOTE: THIS IS UNUSED IF MEMCG IS ENABLED. * * Use mem_cgroup_lruvec() to look up lruvecs. */ struct lruvec __lruvec; unsigned long flags; ZONE_PADDING(_pad2_) /* Per-node vmstats */ struct per_cpu_nodestat __percpu *per_cpu_nodestats; atomic_long_t vm_stat[NR_VM_NODE_STAT_ITEMS];} pg_data_t; |
mem_map
123456789101112131415161718 | // mm/memory.cunsigned long max_mapnr;EXPORT_SYMBOL(max_mapnr);struct page *mem_map;EXPORT_SYMBOL(mem_map);/* * A number of key systems in x86 including ioremap() rely on the assumption * that high_memory defines the upper bound on direct map memory, then end * of ZONE_NORMAL. Under CONFIG_DISCONTIG this means that max_low_pfn and * highstart_pfn must be the same; there must be no gap between ZONE_NORMAL * and ZONE_HIGHMEM. */void *high_memory;EXPORT_SYMBOL(high_memory); |
Linux 物理内存的初始化
- 系统启动时,ARM Linux 内核如何知道系统中有多大的内存空间
- 在 32 bit Linux内核中,用户空间和内核空间的比例通常是3:1,可以修改成2:2吗?
- 物理内存页面如何添加到伙伴系统中,是一页一页添加还是以2的几次幂来添加的?
DDR 简介
- Bank
- 行
- 列


内存节点
内存存储模型:
- UMA (uniform memory access)均匀存储器存取
- NUMA (non-uniform memory access)非均匀存储器存取
使用 struct pglist_data 描述
内存管理区域ZONE
- 为什么要有zone
- zone_type
- struct zone
页表映射
arm32
- 支持四级映射
- 全局目录项 PGD (Page Global Directory)
- 上级目录项 PUD (Page Upper Directory)
- 中间目录项 PMD (Page Middle Directory)
- 页表项 (Page Table)
Linux内核最早是基于x86做的,因此内核代码中常用上面这个术语来表示一级页表,二级页表等
虚拟地址到物理地址的转换

一级页表表项

- Fault
- 错误的表项
- Page table
- 一级页表的表项
- bit[0~1]:用来表示这个页表项是一级页表还是段映射的表项
- PXN:PL1是否可以执行这段代码,为0表示可执行,为1表示不可执行
- NS: non security bit表示安全扩展的比特位
- Domain: 指明所属的域,Linux只用到了3个域
- bits[31:10] Page table base address 指向二级页表的基地址

- Section
- 段映射的段表项
二级页表表项
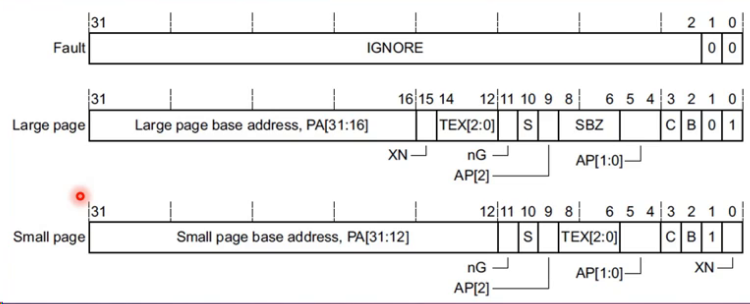
- bit0 禁止执行标志,1表示禁止执行,0表示可执行
- bit1 区分大页还是小页
- C/B bit: 内存区域属性
- TEX[2:0]:内存区域属性
- AP[1:0]: 访问权限
- S: 是否可共享
- nG: 用于TLB
arm64
ARMv8-A架构
- 支持48根地址线
- 访问区域分成两部分(内核区和用户空间区),每个区域256TB
- 支持4KB,16KB和64KB的页,支持3级或者4级映射
ARMv8有两个页表基地址,一个用于用户区一个用于内核区,通过bit63来选择
4KB大小页+4级映射

TODO
- 总结页表相关操作的宏
- start_kernel()->setup_arch()->paging_init()->map_lowmem()
static void __init create_mapping(struct map_desc *md)
kernel image区域建立页表映射,线性映射区域建立页表映射
研究如何建立内核页表的映射
- int remap_pfn_range() 研究如何由vma和虚拟地址以及物理地址pfn这些信息去建立页表映射的
- static int do_anonymous_page 研究这个缺页中断函数来观察:知道了vma和虚拟地址vaddr以及页表项如何来设置用户进程的页表

ARM32的实现方式:平行页表
两套页表,一套为了迎合硬件,一套为了迎合Linux内核

页面分配机制
伙伴系统
- 伙伴算法是按2的幂次方大小进行分配内存块,这些内存被称为伙伴
- 何为伙伴
- 两个块大小相同
- 两个块地址连续
- 两个块必须是同一个大块分离出来的

迁移类型
- 为了解决碎片化的问题,在伙伴系统中引入了迁移类型
- MIGRATE_UNMOVABLE: 在内存中有固定位置,不能随意移动,比如内核分配的内存
- MIGRATE_MOVABLE: 可以随意移动,用户态app分配内存
- MIGRATE_RECLAIMABLE: 不能移动可以删除回收,比如文件映射
- 内存碎片化的产生

page3是被内核自身分配的函数使用了,比如alloc_page(GPF_KERNEL),所以它属于不可移动的页面,尽管其他页面都是空闲页面,page0到page7不能合成一块大的内存块
页面分配和分配掩码
页面核心分配函数
123 | struct page *alloc_pages(gfp_t gfp_mask,unsigned int order)unsigned long __get_free_pages(gfp_t gfp_mask, unsigned int order)alloc_page(gfp_mask) |
gfp_mask标志位


- 页面分配器是基于zone来设计的,因此页面的分配有必要确定哪些zone可以用作本次页面分配,系统会优先使用ZONE_NORMAL,ZONE_HIGHMEM 作为最后手段(仅 32 位系统)
- 页面分配的时候也需要知道当前分配是要从哪个迁移类型中分配内存
zone水位

Linux内核中定义:
123456 | enum zone_watermarks { WMARK_MIN, WMARK_LOW, WMARK_HIGH, NR_WMARK}; |
页面释放函数
123 | void free_pages(unsigned long addr,unsigned int order)__free_page(page) free_page(addr) |
per-cpu高速页面缓存
内核经常请求和释放单个页框,比如网卡驱动等等
页面分配器分配和释放页面的时候需要申请一把锁: zone->lock
- 为了提高单个页框的申请和释放效率,内核建立了per-cpu页面高速缓存池
- 其中存放了若干预先分配好的页框
当请求单个页框时,直接从本地cpu的页框高速缓存池中取出页框
- 不必申请锁
- 不必进行复杂的页框分配操作
(体现了预先建立缓存池的优势,而且是每个CPU有一个独立的缓存)
per-CPU数据结构
- zone中有一个成员pageset字段指向per-cpu的高速缓存
- struct per_cpu_pages数据结构
12345678 | struct per_cpu_pages { int count; /* number of pages in the list */ int high; /* high watermark, emptying needed */ int batch; /* chunk size for buddy add/remove */ /* Lists of pages, one per migrate type stored on the pcp-lists */ struct list_head lists[MIGRATE_PCPTYPES];}; |
slab机制
当在内核中需要分配几十个字节的小块内存的时候,怎么办

12345678910111213141516171819202122232425262728293031323334353637383940414243444546474849505152535455565758596061626364656667686970717273 | /* * Definitions unique to the original Linux SLAB allocator. */struct kmem_cache { struct array_cache __percpu *cpu_cache;/* 1) Cache tunables. Protected by slab_mutex */ unsigned int batchcount; unsigned int limit; unsigned int shared; unsigned int size; struct reciprocal_value reciprocal_buffer_size;/* 2) touched by every alloc & free from the backend */ unsigned int flags; /* constant flags */ unsigned int num; /* # of objs per slab *//* 3) cache_grow/shrink */ /* order of pgs per slab (2^n) */ unsigned int gfporder; /* force GFP flags, e.g. GFP_DMA */ gfp_t allocflags; size_t colour; /* cache colouring range */ unsigned int colour_off; /* colour offset */ struct kmem_cache *freelist_cache; unsigned int freelist_size; /* constructor func */ void (*ctor)(void *obj);/* 4) cache creation/removal */ const char *name; struct list_head list; int refcount; int object_size; int align;/* 5) statistics */ unsigned long num_active; unsigned long num_allocations; unsigned long high_mark; unsigned long grown; unsigned long reaped; unsigned long errors; unsigned long max_freeable; unsigned long node_allocs; unsigned long node_frees; unsigned long node_overflow; atomic_t allochit; atomic_t allocmiss; atomic_t freehit; atomic_t freemiss; /* * If debugging is enabled, then the allocator can add additional * fields and/or padding to every object. size contains the total * object size including these internal fields, the following two * variables contain the offset to the user object and its size. */ int obj_offset; struct memcg_cache_params memcg_params; struct kmem_cache_node *node[MAX_NUMNODES];}; |
- array_cache:这里是指的per-CPU的对象缓存池,每个CPU一个
- 用来建立本地对象缓存池,每个CPU一个,有利于:
- 让对象尽可能的使用同一个CPU上的cache,有利于提高效率
- 不需要额外的自旋锁,避免锁的争用
- 用来建立本地对象缓存池,每个CPU一个,有利于:
12345678910111213141516171819202122232425262728293031323334353637383940414243444546474849505152535455565758596061 | /* * struct array_cache * * Purpose: * - LIFO ordering, to hand out cache-warm objects from _alloc * - reduce the number of linked list operations * - reduce spinlock operations * * The limit is stored in the per-cpu structure to reduce the data cache * footprint. * */struct array_cache { unsigned int avail; unsigned int limit; unsigned int batchcount; unsigned int touched; // entry用来保存空闲对象的实体 void *entry[]; /* * Must have this definition in here for the proper * alignment of array_cache. Also simplifies accessing * the entries. * * Entries should not be directly dereferenced as * entries belonging to slabs marked pfmemalloc will * have the lower bits set SLAB_OBJ_PFMEMALLOC */};/* * The slab lists for all objects. */struct kmem_cache_node { spinlock_t list_lock; struct list_head slabs_partial; /* partial list first, better asm code */ struct list_head slabs_full; struct list_head slabs_free; unsigned long free_objects; unsigned int free_limit; unsigned int colour_next; /* Per-node cache coloring */ struct array_cache *shared; /* shared per node */ struct alien_cache **alien; /* on other nodes */ unsigned long next_reap; /* updated without locking */ int free_touched; /* updated without locking */ unsigned long nr_partial; struct list_head partial; atomic_long_t nr_slabs; atomic_long_t total_objects; struct list_head full;}; |
- batchcount:表示当本地的对象缓存池为空时,需要从共享缓存池中获取batchcount个对象到本地缓存池
- limit: 当本地对象缓存池空闲数目大于limit时,需要释放一些对象
- shared: 用于多核系统
- size: 表示对象的长度
- flags: 对象分配掩码
- num: 一个slab中可以有多少个对象
- gfporder: 一个slab占用多个2的order次方的物理页面
- colour: 表示一个slab使用多少个cache line用于着色(cache colouring)
- freelist_size:每个对象要占用1字节来存放freelist
- name: 描述符的名称
- object_size:对象实际大小
- align: 对齐的长度
一个slab的组成

slab运行机制

slab的回收
- 如果一个slab描述符中有很多空闲对象,那么系统是否要回收一些空闲的缓存对象从而释放内存归还系统呢?
- 使用kmem_cache_free释放一个对象,当发现本地和共享对象缓冲池中的空闲对象数目ac->avail大于等于缓冲池的极限值ac->limit时,系统会主动释放batchcount个对象
- slab系统还注册了一个定时器,定时去扫描所有的slab描述符,回收一部分空闲对象
kmalloc函数
- kmalloc()函数的核心是slab机制
- 按照内存块的2的order来创建多个slab描述符
- void *kmalloc(size_t size, gfp_t flags)
- void kfree(const void*)
vmalloc

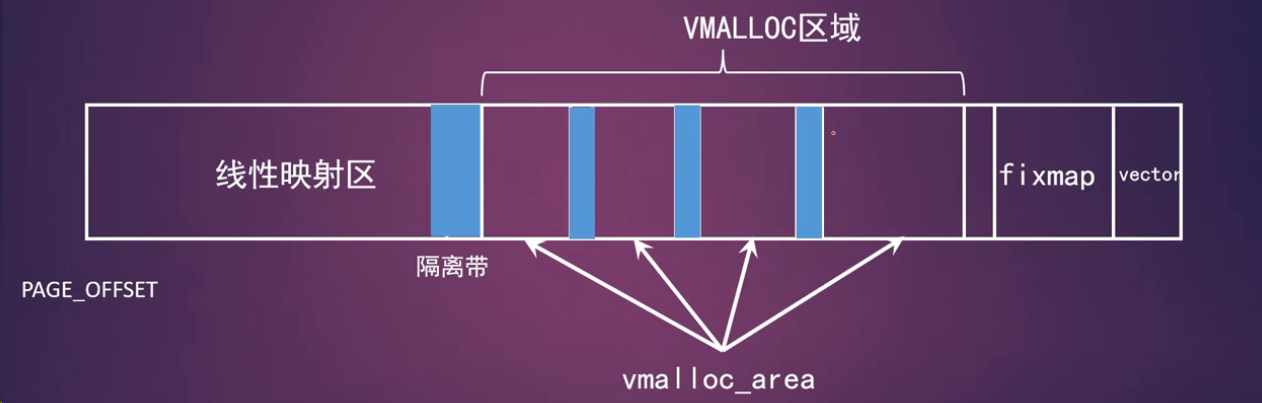
vmalloc接口函数
12 | void *vmalloc(unsigned long size);void vfree(const void *addr); |
vmalloc分配过程中是可以睡眠的,因此不能用在中断上下文中
VMA操作

12345678910111213141516171819202122232425262728293031323334353637383940414243444546474849505152535455565758596061 | struct vm_area_struct { /* The first cache line has the info for VMA tree walking. */ unsigned long vm_start; /* Our start address within vm_mm. */ unsigned long vm_end; /* The first byte after our end address within vm_mm. */ /* linked list of VM areas per task, sorted by address */ struct vm_area_struct *vm_next, *vm_prev; struct rb_node vm_rb; /* * Largest free memory gap in bytes to the left of this VMA. * Either between this VMA and vma->vm_prev, or between one of the * VMAs below us in the VMA rbtree and its ->vm_prev. This helps * get_unmapped_area find a free area of the right size. */ unsigned long rb_subtree_gap; /* Second cache line starts here. */ struct mm_struct *vm_mm; /* The address space we belong to. */ pgprot_t vm_page_prot; /* Access permissions of this VMA. */ unsigned long vm_flags; /* Flags, see mm.h. */ /* * For areas with an address space and backing store, * linkage into the address_space->i_mmap interval tree. */ struct { struct rb_node rb; unsigned long rb_subtree_last; } shared; /* * A file's MAP_PRIVATE vma can be in both i_mmap tree and anon_vma * list, after a COW of one of the file pages. A MAP_SHARED vma * can only be in the i_mmap tree. An anonymous MAP_PRIVATE, stack * or brk vma (with NULL file) can only be in an anon_vma list. */ struct list_head anon_vma_chain; /* Serialized by mmap_sem & * page_table_lock */ struct anon_vma *anon_vma; /* Serialized by page_table_lock */ /* Function pointers to deal with this struct. */ const struct vm_operations_struct *vm_ops; /* Information about our backing store: */ unsigned long vm_pgoff; /* Offset (within vm_file) in PAGE_SIZE units, *not* PAGE_CACHE_SIZE */ struct file * vm_file; /* File we map to (can be NULL). */ void * vm_private_data; /* was vm_pte (shared mem) */ struct vm_region *vm_region; /* NOMMU mapping region */ struct mempolicy *vm_policy; /* NUMA policy for the VMA */}; |

1234 | struct vm_area_struct *find_vma(struct mm_struct *mm, unsigned long addr);struct vm_area_struct * find_vma_intersection(struct mm_struct * mm, unsigned long start_addr, unsigned long end_addr);struct vm_area_struct * find_vma_prev(struct mm_struct * mm, unsigned long addr, struct vm_area_struct **pprev); |

123456 | int insert_vm_struct(struct mm_struct *mm, struct vm_area_struct *vma)struct vm_area_struct *vma_merge(struct mm_struct *mm, struct vm_area_struct *prev, unsigned long addr, unsigned long end, unsigned long vm_flags, struct anon_vma *anon_vma, struct file *file, pgoff_t pgoff, struct mempolicy *policy) |

malloc
malloc 全称是memory allocation,中文名动态分配,用户空间主要用来分配虚拟内存的API
calloc 在动态分配完内存后,自动初始化改内存空间为0,而malloc不初始化,里面的数据是随机的垃圾数据
realloc 修改一个原先已经分配的内存块的大小,可以使一块内存的扩大或缩小
malloc是c库封装的API,最终调用brk系统调用
glibc里维护了一个小仓库,malloc函数的实现为用户进程维护了一个本地小仓库,当该进程需要使用更多的内存时就向这个小仓库要货,小仓库存量不足时就通过该代理商brk向内核批发
malloc()想象成零售,那么brk就是代理商
brk系统调用
1 | SYSCALL_DEFINE1(brk, unsigned long, brk) |
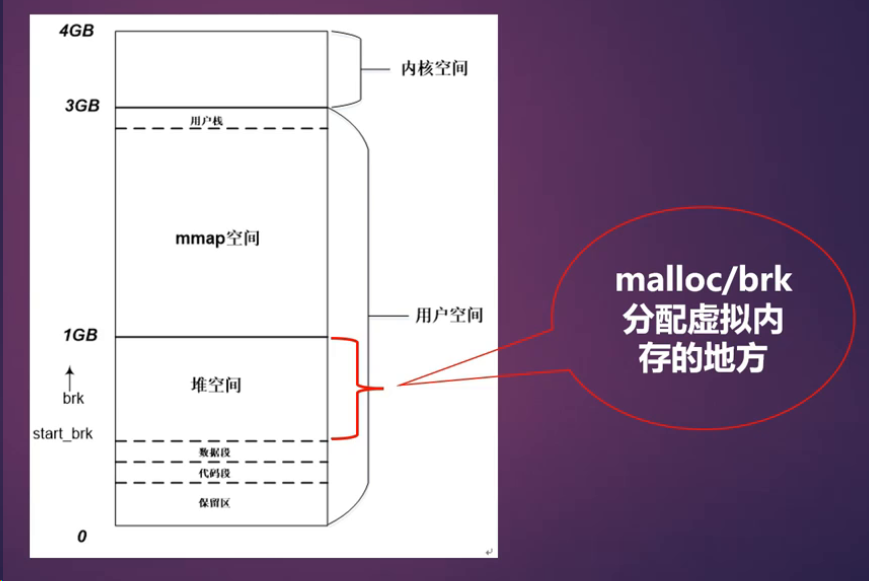
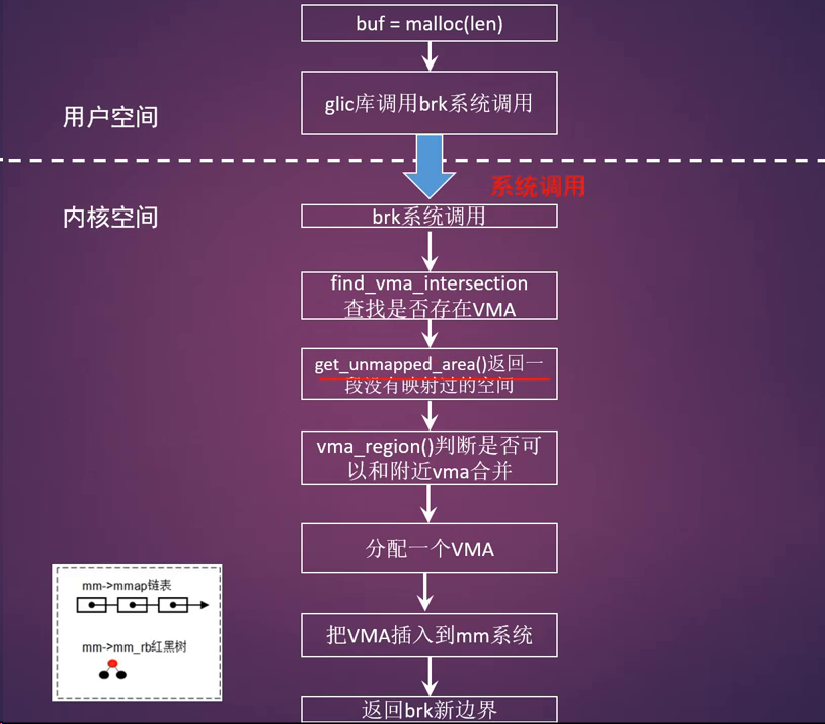
- 上图在进程的地址空间堆空间中查找一段空闲空间,然后创建一个VMA,然后就返回
- 按需分配(on-demand page)
- malloc分配的内存可能长时间不使用,所以进程分配内存马上就分配物理空间其实不是一个好办法
- 解决办法: 缺页中断,当进程真的需要访问这些虚拟页面的时候,情非得已才去创建物理内存
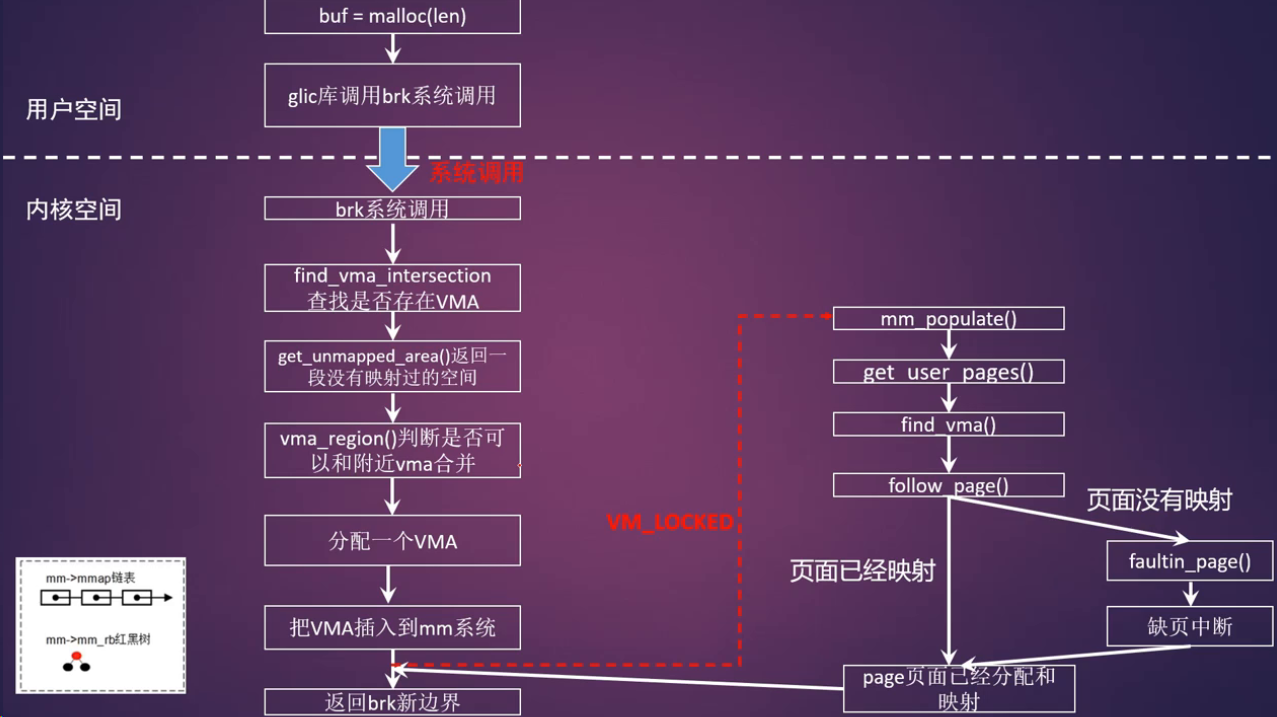
mlock系统调用
- 系统调用mlock允许程序在物理内存上锁住它的部分或全部地址空间,调用mlock会马上为虚拟内存分配物理内存
- 将阻止Linux将这个内存页调度到交换空间(swap space)
- 在brk函数实现中,最后返回虚拟内存地址的时候,会去检查一个变量VM_LOCKED,这个VM_LOCKED通常从mlock系统调用中设置而来
- 如果有,那么需要调用mm_populate()马上分配物理内存并建立映射
- 一般情况是:一直将分配物理页面的工作推延到用户进程需要访问这些虚拟页面时,发生了缺页中断才会分配物理内存,并和虚拟地址建立映射关系

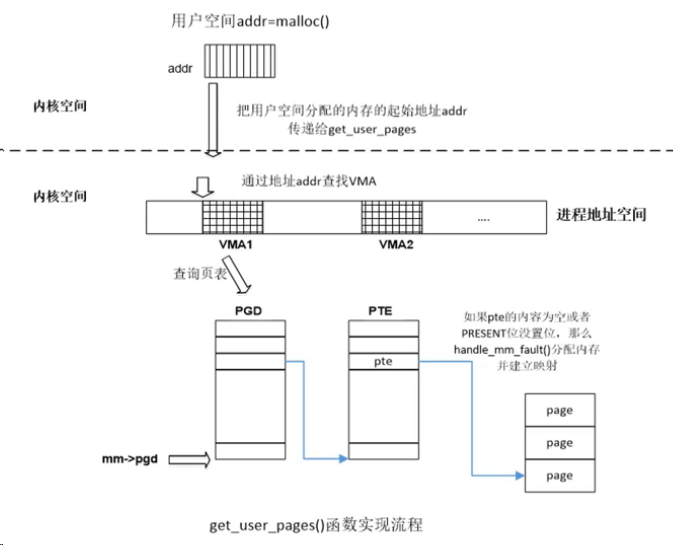
get_user_pages()函数
- 一个很重要分配物理内存的接口函数,有很多驱动程序使用这个API来为用户态程序分配物理内存
follow_page()函数
- 返回用户进程地址空间VMA中已有映射过的normal mapping页面的struct page数据结构
vm_normal_page()函数
- 该函数把page页面分为两个阵营,一个是normal page,另一个是special page
- normal page通常指正常mapping的页面,比如匿名页面,page cache和共享内存页面
- special page通常指不正常mapping的页面,这些页面不希望参与内存管理的回收或者合并的功能,例如映射如下特性的页面:
- VM_IO : 为I/O设备映射内存
- VM_PEN_MAP : 纯PFN映射
- VM_MIXEDMAP : 固定映射
总结
- malloc函数其实是为用户空间分配进程地址空间,用内核术语来说就是分配一块VMA,相当于一个空的纸箱子,那么什么时候往箱子里装东西?两种方式:
- 一种是到了真正使用箱子的时候才往里面装东西
- 另一种是分配箱子的时候就装了你想要的东西
- 两个进程的malloc分配的虚拟地址是一样的,会打架吗?
- 每个用户进程有自己的一份页表,每个进程有一个mm_struct数据结构,包含一个属于进程自己的页表,一个管理VMA的红黑树和链表
- 即使进程A和进程B使用malloc分配内存返回的相同的虚拟地址,但其实他们是两个不同的VMA,分别被不同的两套页表来管理
mmap
123 | void *mmap(void *addr,size_t length,int prot,int flags,int fd,off_t offset);int munmap(void *addr,size_t length); |
- addr : 用于指定映射到进程地址空间的起始地址,为了应用程序的可移植性,一般设置为NULL,让内核选择一个合适的地址
- length: 表示映射到进程地址空间的大小
- prot : 用于设置内存映射区域的读写属性
- PROT_EXEC:表示映射的页面是可以执行的
- PROT_READ:表示映射的页面是可以读取的
- PROT_WRITE:表示映射的页面是可以写入的
- PROT_NONE: 表示映射的页面是不可访问的
- flags:用于设置内存映射的属性,例如共享映射,私有映射等
- MAP_SHARED: 创建一个共享映射的区域,多个进程可以通过共享映射的方式来映射一个文件,这样其他进程也可以看到映射内容的改变,修改后的内容会同步到磁盘文件中
- MAP_PRIVATE: 创建一个私有的写时复制的映射,多个进程可以通过私有映射的方式来映射一个文件,这样其他进程不会看到映射内容的改变,修改后的内容也不会同步到磁盘文件里
- MAP_ANONYMOUS: 创建一个匿名映射,即没有关联到文件的映射
- MAP_FIXED: 使用参数addr创建映射,如果在内核中无法映射指定的地址addr,那么mmap会返回失败,参数addr要求按页对齐。如果addr和length指定的进程地址空间和已有的VMA区域重叠,那么内核会调用do_munmap()函数把这段重叠的区域销毁,然后重新映射新的内容
- MAP_POPULATE: 对于文件映射来说,会提前预读文件内容到映射区域,该特性只支持私用映射。
- fd: 表示这是一个文件映射,fd是打开的文件句柄
- offset: 在文件映射时,表示文件偏移量
文件映射和匿名映射
- 匿名映射: 没有映射对应的相关文件,这种映射的内存区域的内容会被初始化为0
- 文件映射:映射和实际文件相关联,通常是把文件的内容映射到地址空间,这样应用程序可以像操作系统进程空间一样读写文件
私有映射和共享映射
- 私有映射: 创建的映射只能自己看到,其他的进程不能看到映射内容的改变
- 共享映射:创建的映射其他进程可以看到映射内容的改变,如果以共享的方式打开一个文件的话,修改后的内容会同步到磁盘文件中


缺页中断
分页机制
- MMU
- 页表项中的PTE_PRESENT比特位

PTE页表项 ARM32的MMU中有如下两个与存储访问失效相关的寄存器
- 失效状态寄存器(Data Fault Status Register, FSR)
- 失效地址寄存器(Data Fault Address Register, FAR)
ARMv7汇编处理流程为 vectors_start -> vector_dabt -> datb_user / dabt_svc -> dabt_helpper -> v7_early_abort
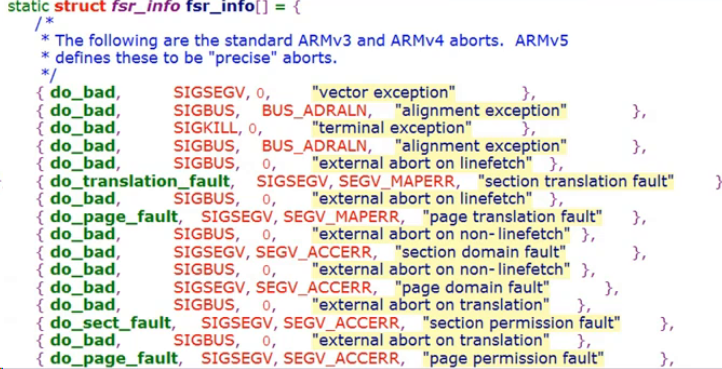
struct fsr_info数据结构用于描述一条失效状态对应的处理方案
fs_info[]数组列出了常见的地址失效处理方案

问题1:什么是匿名页面?
- 在Linux内核中没有关联到文件映射的页面称为匿名页面(Anonymous Page,简称anon page)。比如malloc分配的页面
问题2:为什么需要匿名页面的缺页中断?
- 如果没有匿名页面缺页中断,那么你在用户空间使用malloc()这个API来分配虚拟内存,那么在内核中都需要实实在在的为其分配物理内存。主要的问题就是浪费,因为很多时候应用程序分配虚拟内存并不会马上使用,所以没有必要马上就满足应用程序的需求
问题3:匿名页面缺页中断发生的条件是什么?
- 当pte页表项中PRESENT没有置位
- pte内容为空
- 没有指定vma->vm_ops->fault()函数指针
满足上述三个条件我们就判断现在是匿名页面缺页中断了,处理函数是:do_anonymous_page

- 问题1:什么是文件映射?
- 和文件相连的映射,其实就是文件映射,这个是和匿名映射相对应的。把文件的内容映射到进程地址空间里面
- 问题2:哪些类型的映射会产生文件映射的缺页中断?
- 对应的文件映射主要是普通文件的映射,比如视频播放器读取一个视频文件
- 还有一种情况就是,设备驱动通过mmap把设备DMA buffer映射到进程地址空间里
- 在handle_pte_fault()函数里怎么判断是文件映射
- 当页面不在内存
- 页表项内容为空
- VMA定义了fault方法函数(vma->vm_ops->fault())
写缺页中断
- 写缺页中断是最复杂的情况,也是最常用的情形
- 写时复制技术(COW)
- 在fork子进程的时候,内核不需要复制父进程的整个用户空间内容给予子进程而是让父子进程共享父进程的地址空间,这样就省去了非常耗时的拷贝动作,而仅仅是拷贝页表即可
- 当父子进程有一方需要写入的时候,数据才会被复制,从而父子进程才会拥有各自的副本。所以,这里的do-wp-page函数就是处理这种共享问题
- do_wp_page()的判断条件是什么
- 当PTE_PRESETN位 置位 了然后缺页处理flags标志位是显示写保护错误(这个写保护错误,通常硬件是会报告的)

- 总的来说,这个过程相当复杂,需要处理很多种情况:
- normal mapping页面和special mapping页面
- 纯粹的匿名页面,这个名词是编造的,也就是剔除了KSM的匿名页面
- 单身匿名页面,这个名词也是编造的,就是只有一个进程的虚拟页面映射了这个匿名页面,即mapcount=0
- 非单身匿名页面
- 可写共享匿名页面,这个通常指的是具有可写属性,并且是share的页面,通常是page cache
总结
- 缺页中断发生后,根据pte页表项的PRESETN位,pte内容是否为空(pte_none()宏)以及是否文件映射等条件,相应的处理函数如下:
- 匿名页面缺页中断 do_anonymous_page()
- 判断条件
- pte页表项中PRESENT没有置位
- pte内容为空
- 没有指定vma->vm_ops->fault()函数指针
- 应用场合: malloc()分配内存
- 判断条件
- 文件映射缺页中断do_fault()
- 判断条件
- pte页表中的PRESENT没有置位
- pte内容为空且制定了vma->vm_ops->fault()函数指针
- do_fault()属于在文件映射中发生的缺页中断的情况
- 如果仅发生读错误,那么调用do_read_fault()函数去读取这个页面
- 如果在私有映射VMA中发生写保护错误,那么发生写时复制,新分配一个页面new_page,旧页面的内容要复制到新页面中,利用新页面生成一个PTE entry并设置到硬件页表项中,这就是所谓的写时复制COW
- 如果写保护错误发生在共享映射VMA中,那么就产生了脏页,调用系统的回写机制来回写这个脏页
- 应用场景:
- 使用mmap读文件内容,例如驱动中使用mmap映射设备内存到用户空间
- 动态库映射,例如不同的进程可以通过文件映射来共享一个动态库
- 判断条件
- swap缺页中断do_swap_page()
- 写时复制COW缺页中断do_wp_page()
- do_wp_page()最终处理有两种情况
- resue复用old_page: 单身匿名页面和可写的共享页面
- gotten写时复制:非单身匿名页面,只读或者非共享的文件映射页面
- 判断条件:pte页表项中的PRESENT置位了且发生写错误缺页中断
- 应用场景:fork, 父进程fork子进程,父子进程都共享父进程的匿名页面,当其中一方需要修改内容时,COW便会发生
- do_wp_page()最终处理有两种情况
- 匿名页面缺页中断 do_anonymous_page()
pages数据结构
当开启了MMU之后,CPU访问内存的最小单位为页(Page)
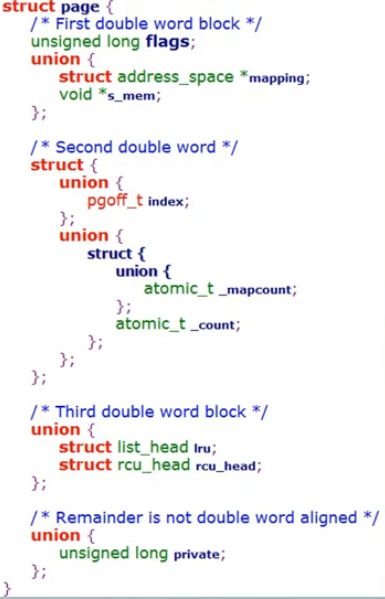
- flag标志:PG_*标志位
- 定义在include/linux/page-flags.h

arm vexpress平台

- _count字段
- 当_count的值为0时,表示该page页面为空闲或即将要被释放的页面
- 当_count的值大于0时,表示该page页面已经被分配且内核正在使用,暂时不会被释放
1234 | static inline void get_page(struct page *page);void put_page(struct page *page); |
_mapcount字段
_mapcount引用技术表示这个页面被进程映射的个数,即已经映射了多少个用户pte页表。在32位Linux内核中,每个用户进程都拥有3GB的虚拟空间和一份独立的页表,所以有可能出现多个用户进程地址空间同时映射到一个物理页面的情况,RMAP反向映射系统就是利用这个特性来实现的。_mapcount引用计数主要用于RMAP反向映射系统中。
- _mapcount==-1 表示没有pte映射到页面
- _mapcount==0 表示匿名页面刚分配时的初始状态(尚未映射到用户进程)
使用:
内核代码不会直接去检查count和mapcount的个数,而是采用两个宏
static inline int page_mapcount(struct page *page)
static inline int page_count(struct page *page)
mapping 字段
- 当这个页面用于文件缓存即page cache时候,mapping指向和这个page cache相关联的address_space对象,这个address_space对象是属于内存对象(比如索引节点的页面集合)
- 当这个页面用于匿名页面(Anonymous Page)的时候,mapping指向一个anon_vma数据结构,主要是用于反向映射(Reverse Mapping)
lru字段
- 用在页面回收的LRU链表算法中,LRU链表算法定义了多个链表
- 当页面用于slab时,该字段被复用,用来把一个slab添加到slab满链表、slab空闲链表和slab部分链表中
virtual字段
- 一个指向页所对应的虚拟地址的指针
struct page的意义
- 内核知道当前这个页面的状态(通过flags字段)
- 内核需要知道一个页面是否空闲即有没有分配出去,有多少个进程或者内存路径使用了这个页面(使用count和mapcount引用计数)
- 内核知道了谁在使用了这个页面,比如使用者是通过用户空间进程的匿名页面还是page cache?(通过mapping字段)
- 内核知道这个页面是否被slab机制使用(通过lru,s_mem等字段)
- 内核知道这个页面是否线性映射(通过virtual字段)
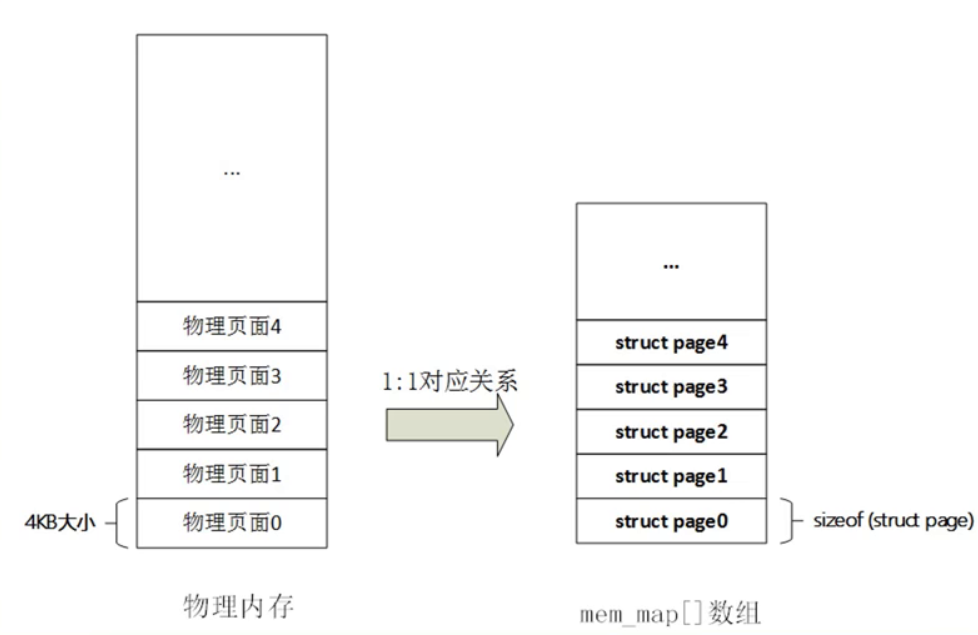
- 页面锁PG_Locked
- struct page数据结构成员flags定义了一个标志位PG_locked,内核通常利用PG_locked来设置一个页面锁
- lock_page()函数用于申请页面锁,如果页面锁被其他进程占用了,那么就会睡眠等待
- trylock_page()如果返回false表示获取锁失败,返回true表示获取锁成功
- trylock_page()不会去睡眠等待,只是用来做一下判断
- struct page数据结构成员flags定义了一个标志位PG_locked,内核通常利用PG_locked来设置一个页面锁
RMAP 反向映射机制
正向映射
- 从虚拟地址到物理地址,沿着MMU硬件的脚步
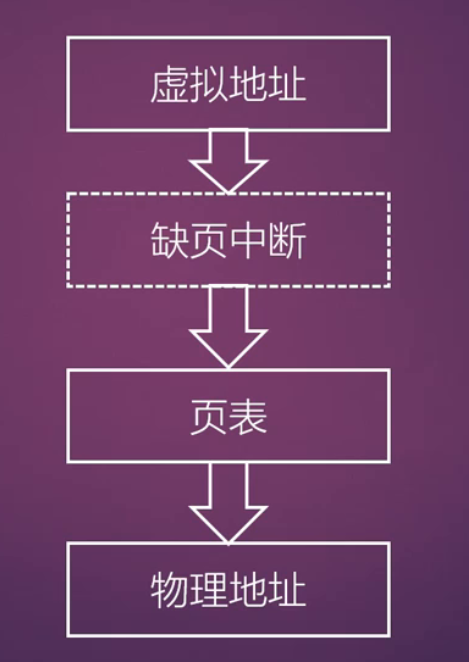
RMAP反向映射 当物理内存短缺时?
- 虚拟内存常常大于物理内存
- 把暂时不用的物理内存swap到交换分区
如何判断哪些物理内存暂时不用?
- LRU算法
- 第二次机会法
Linux 2.4内核的做法
- 遍历所有进程的VMA来确定某个物理页面映射的pte
反向映射的设计目标:

反向映射用到的数据结构:
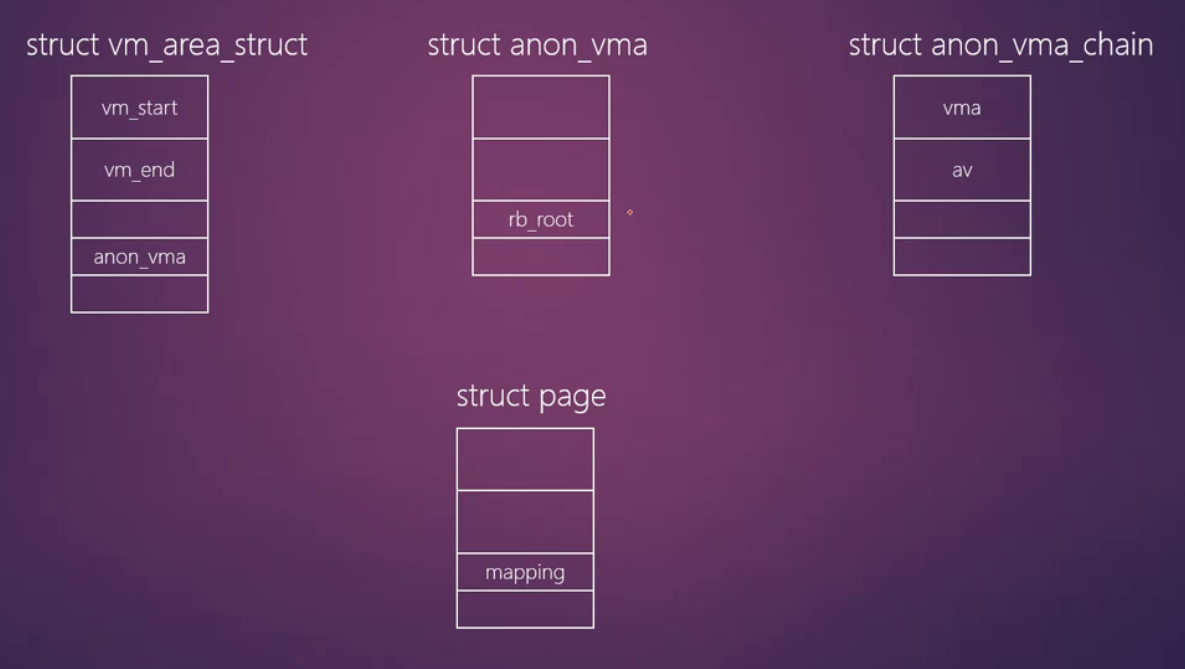
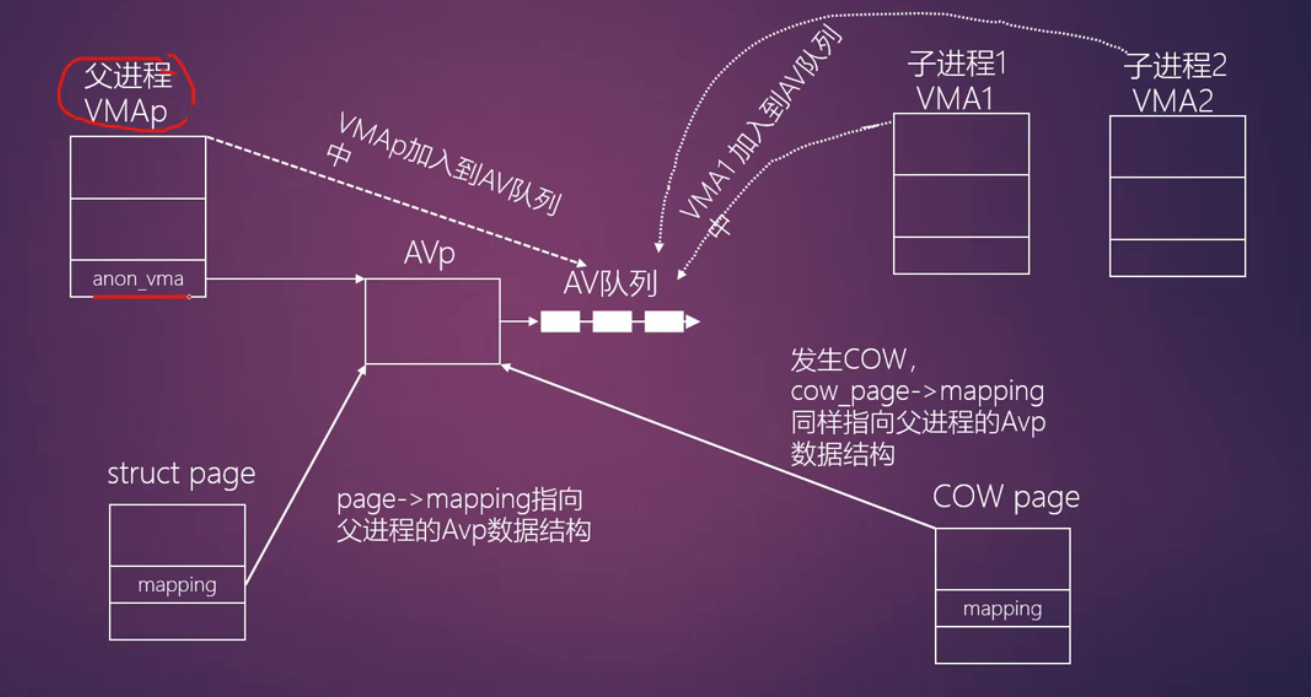
RMAP四部曲(以Linux 2.6.11为例)
父进程分配匿名页面
- do_anonymous_page()->page_add_anon_rmap()
- page_add_anon_rmap()
- page->mapping指向VMA的anon_vma数据结构
- 计算page->index
父进程创建子进程
- do_fork()->copy_mm()->dump_mm(),把父进程所有的VMA复制到子进程对应的VMA中
- anon_vma_link(): 把子进程的VMA加入到父进程的vma->anon_vma->head链表中
子进程发生COW
- 当父子进程共享匿名页面,子进程的VMA发生COW
缺页中断->handle_pte_fault()->do_wp_page()->分配一个新的匿名页面->page_add_anon_rmap()
新分配的匿名页面page->mapping指向父进程vma->anon_vma
RMAP应用
- 页面回收:断开所有映射的用户PTE才能回收页面
- 页面迁移:断开所有映射的用户PTE
缺陷:

优化,降低锁的粒度
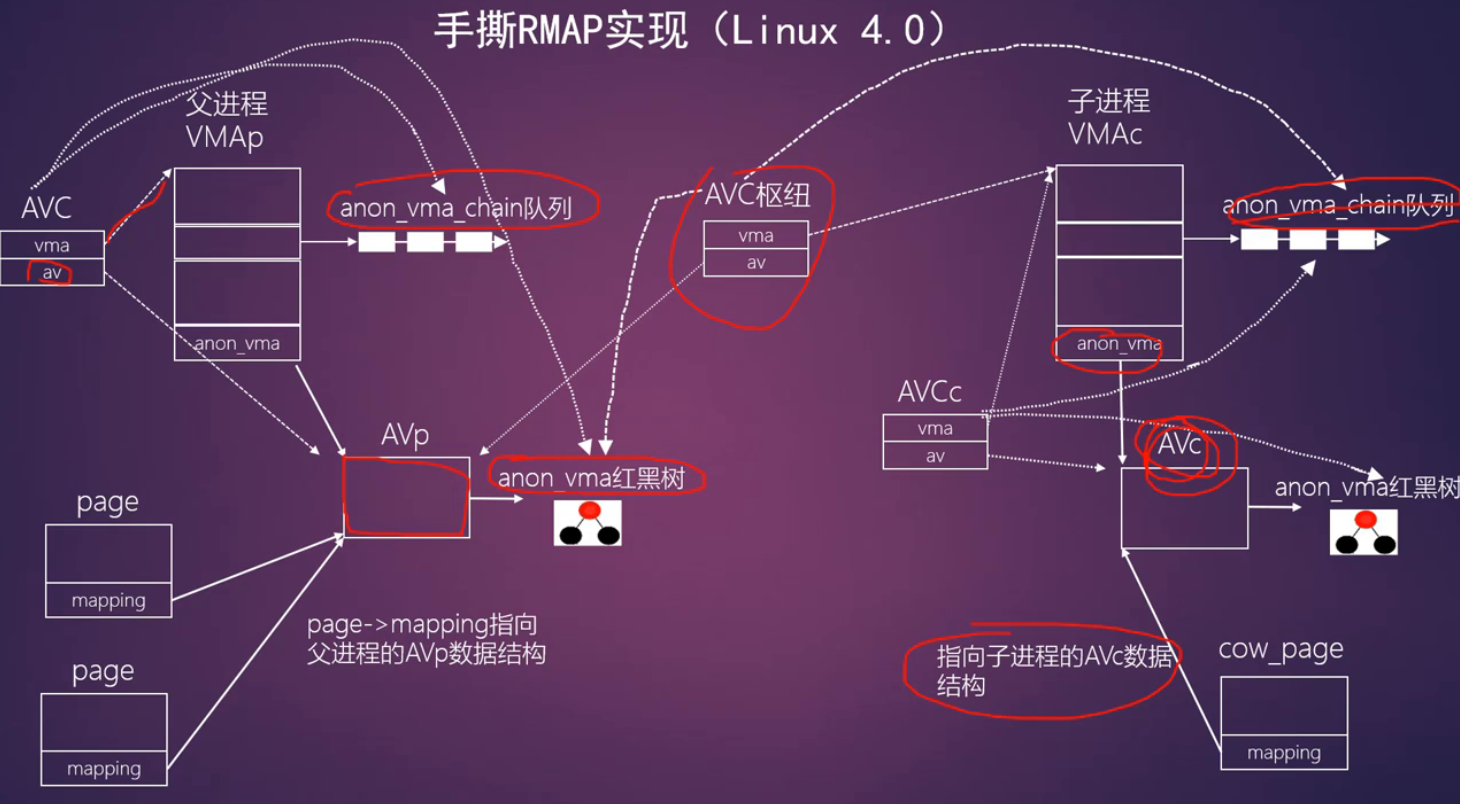
- 反向映射总结
- 提高页面回收效率
- 消耗一定内存空间,典型的以空间换时间
- 连接虚拟内存管理和物理内存管理的一个桥梁
页面回收
页面置换(page replacement)
页面回收(page reclaim)
页面置换其他例子
- 处理器高速缓存cache
- web服务器
页面回收算法介绍
- 最优页面置换算法
- 先进先出页面置换算法
- 最近未使用页面置换算法
- LRU算法(最近最少使用页面置换算法Least Recently Used)
- 利用局部性原理
- 维护链表
- 新页面加入到链表头部
- 每当链表中的页面被访问,该页面加入到链表头部
- 每当需要页面置换的时候,从链表尾部取页面
- 第二次机会法
- 给页面第二次可以被访问的机会
- 时钟页面置换算法
- 工作集算法
Linux内核中使用的页面回收算法
- LRU链表
- 不活跃匿名页面链表 LRU_INACTIVE_ANON
- 活跃匿名页面链表LRU_ACTIVE_ANON
- 不活跃文件映射页面链表LRU_INACTIVE_FILE
- 活跃文件映射页面链表LRU_ACTIVE_FILE
- 不可回收页面链表LRU_UNEVICTABLE
- LRU链表

LRU基于zone实现的。每个zone有一套完整的LRU链表
第二次机会法
- LRU算法缺点:没有考虑该页面的频繁使用的情况,页面依然会被踢出LRU链表
- 第二次机会法:
- 设置了一个访问状态位(硬件控制的比特位)
- 要检查页面的访问位
- 如果是0,立刻踢出LRU链表
- 如果是1,表示这期间又被访问过了,这时清除这个访问状态位,然后把这个页面重新添加到链表头,和新加入的页面一样
- Linux内核使用如下几个状态位来实现第二次机会法:
- PTE_YOUNG 硬件比特位,当一个页面被访问过,硬件会自动设置这个比特位
- PG_active 软件比特位
- PG_referenced 软件比特位
Linux页面回收框图


匿名页面回收过程:
page cache的页面回收流程

LRU链表的迁移
- LRU链表可以在活跃链表和不活跃链表中迁移
- 主要使用的软硬件比特位
- PTE_YOUNG: 硬件比特位,当一个页面被访问过,硬件会自动设置这个比特位
- PG_active: 软件比特位
- PG_referenced: 软件比特位
- 主要辅助函数
- mark_page_accessed(): 主要是用来标记页面已经被访问了,然后设置PG_active和PG_referenced
- page_referenced():判断page是否被访问引用过,返回的访问引用pte的个数,利用反向映射RMAP系统来统计访问引用pte的个数
- page_check_references()
kswapd内核线程
- 负责在内存不足的时候异步回收页面
- 每个NUMA内存节点创建一个kswapd内核线程
- alloc_pages()在低水位(ALLOC_WMARK_LOW)中无法分配出内存,这时分配内存函数会调用wakeup_kswapd()来唤醒kswapd内核线程
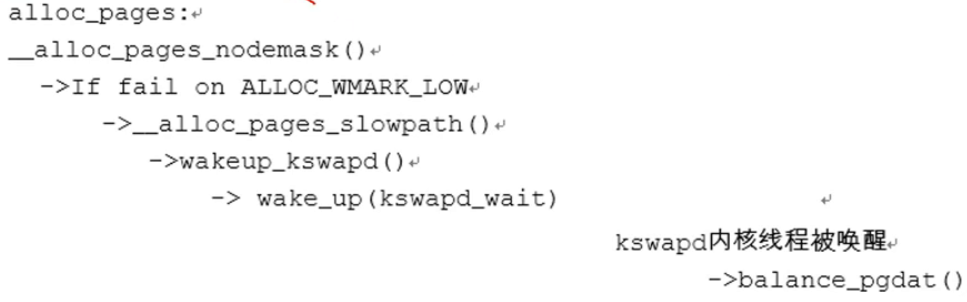
- 当zone处于高水位时会让kswapd睡眠
页面回收详细流程图

匿名页面的生命周期
- maclloc/mmap接口分配的内存->do_anonymous_page()
- 写时复制:当缺页中断出现写保护错误时,新分配的页面是匿名页面
- do_swap_page() 从swap分区读回数据时会新分配匿名页面
- 迁移页面
分配
- do_anonymous_page()分配一个匿名页面anon_page为例子,anon_page刚分配的状态如下:
- page->_count = 1
- page->_mapcount=0
- 设置PG_swapbacked标志位
- 加入LRU_ACTIVE_ANON链表里
- page->mapping指向VMA中的anon_vma数据结构
使用
- 匿名页面在缺页中分配完成之后,就建立了进程虚拟地址空间VMA和物理页面的映射关系,用户进程访问虚拟地址即访问到匿名页面的内容
换出
活跃链表->不活跃链表
第一次扫描不活跃链表
- add_to_swap()函数会为该页分配swap分区空间

add_to_swap - try_to_unmap()

try_to_unmap - pageout()

第二次扫描不活跃链表
假设第二次扫描不活跃链表时,该页写入swap分区已经完成。Block layer层的回调函数end_swap_bio_write()->end_page_writeback()会完成如下动作:
- 清除PG_writeback标志位
- 唤醒等待在该页PG_writeback的线程,见wake_up_page(page,PG_writeback)函数
shrink_page_list()->__remove_mapping()函数作用如下
- page_freeze_refs(page,2)判断当前page->_count是否为2,并且将该计数设置为0
- 清PG_swapcache标志位
- 清PG_locked标志位
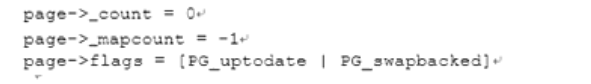
__remove_mapping
最后把page加入free_page链表中,释放该页,因此该anon_page页的状态是页面的内容已经写入swap分区,实际物理页面已经释放
匿名页面的换入
- 匿名页面被换出到swap分区后,如果应用程序需要读写这个页面,缺页中断发生,因为pte中的present比特位显示该页不在内存中,但pte表项不为空,说明该页在swap分区中,因此调用do_swap_page()函数重新读入该页的内容
匿名页面的释放
- 当用户进程关闭或者退出时,会扫描这个用户进程所有的VMAs,并会清理这些VMAs,如果符合释放标准,相关页面会被释放

页面迁移
NUMA:Non-Uniform Memory Access 非统一内存访问
每个处理器有自己的本地内存(Node Local Memory)。
也可以访问其他处理器的内存(Remote Memory),但速度更慢。
常见于多路服务器、大型多核系统。

UMA:Uniform Memory Access 统一内存访问
所有处理器共享一块物理内存。
访问速度一致,也就是 访问任意内存的延迟是相同的。
常见于小型多核系统、对称多处理器系统(SMP)。
libnuma

迁移一个进程的所有页面从一个内存结点到另外一个内存结点
pid 进程的PID
maxnode: node的最大数量
old_nodes: 指向nodes的一个bit mask,这是进程所在的nodes
new_nodes: 指向要迁移目的地的一个node mask

迁移进程的部分页面到新的内存结点
migrae_pages

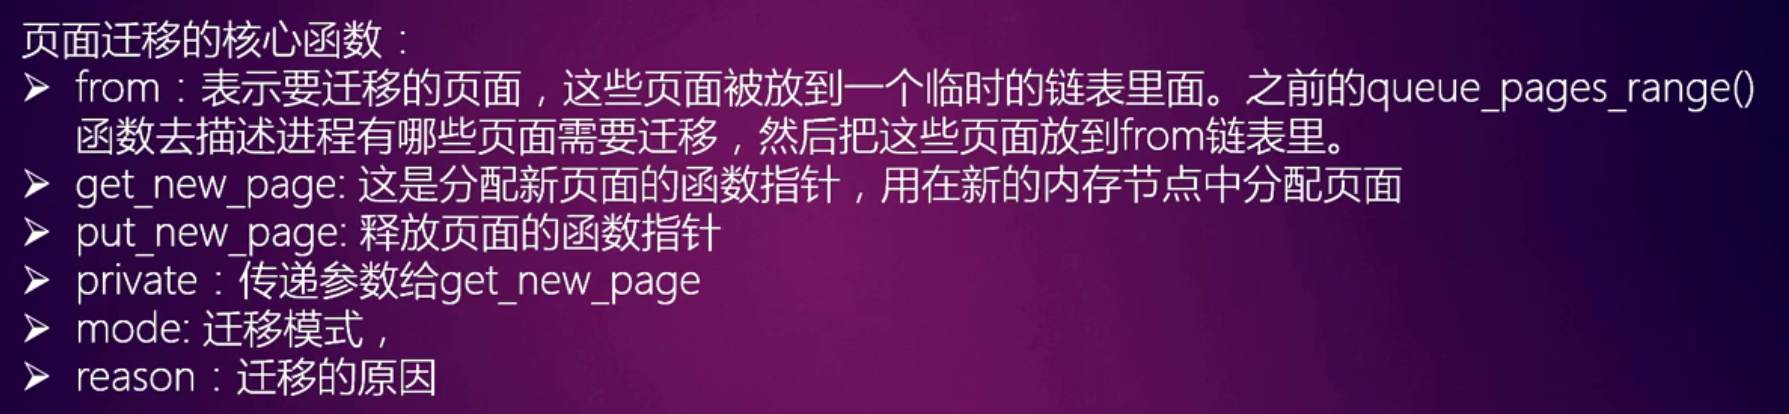

MIGRATE_ASYNC 异步模式,不会阻塞
MIGRATE_SYNC 同步模式,过程会阻塞

页面迁移的流程

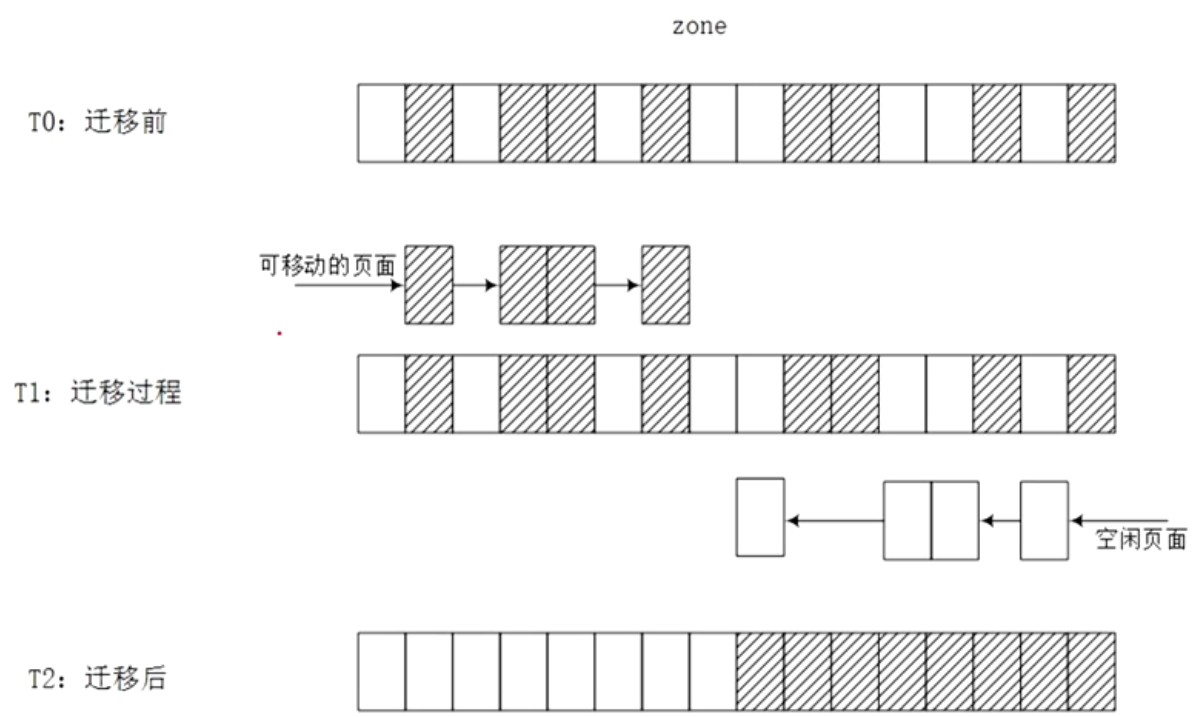
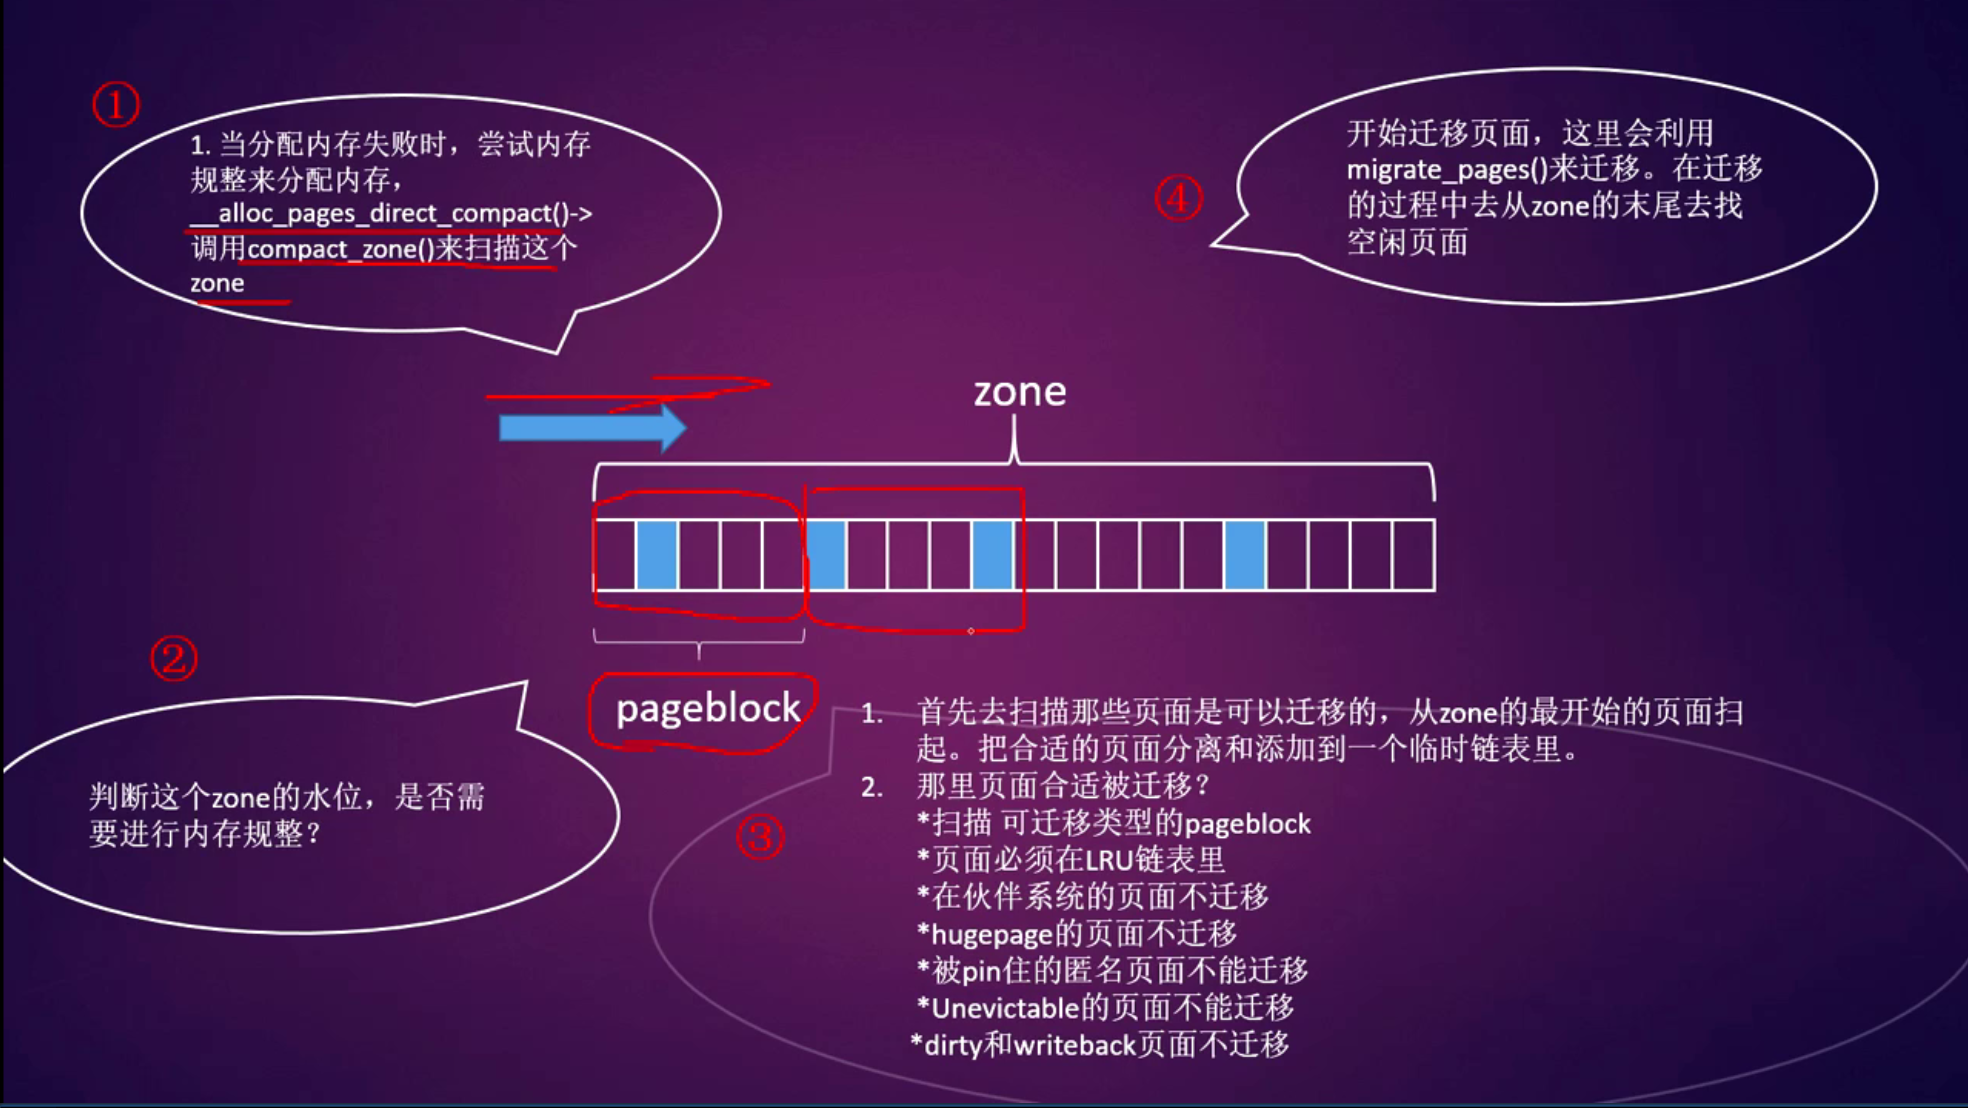
内存规整
memory compaction
内存碎片换产生的原因
- Linux内核的物理内存是由伙伴系统来管理的
- 伙伴系统由11个2的order次方的链表组成,order从0~10
- 伙伴系统有切蛋糕的习惯
- 伙伴系统可以有神奇的修复功能
KSM

如何使用KSM
- 使能KSM:
- madvise(addr,length,MADV_MERGEABLE)
- 关闭KSM:
- madvise(addr,length,MADV_UNMERGEABLE)
- android的bionic库中的mmap函数默认打开了KSM

KSM的统计计数
- run : 这个结点写1,表示启动ksmd内核线程,写0表示要停止ksmd内核线程
- pages_to_scan:单次扫描的页数,ksmd内核线程每次被唤醒之后,会扫描多少个页面
- sleep_millisecs: ksmd在下一次扫描前睡眠多长时间,单位毫秒
- pages_shared: 共享的页面数,如果1000个页面均为同一个内容,然后合并成一个页面,这里pages_shared等于1
- pages_sharing: 可共享的页面数,如果1000个页面合并成一个页面,那么pages_sharing就是1000
- pages_unshared:当前没有合并的页面数量,通常是unstable页面的数量
- full_scans:从头到尾扫描的次数